
GPU Infrastructure Lead - Systems Integrator
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
Prepare application
- Draft this with your agent
- Open in Claude
- Open in ChatGPT
Role details
Tech stack
+3 more
Job description
Join a pioneering compute infrastructure technology company building the platforms and tools that power the rapidly evolving AI compute market. The organisation develops financial and settlement infrastructure for compute, including technology that connects buyers with GPU capacity, while building automated systems to validate, benchmark, and certify large-scale GPU clusters.
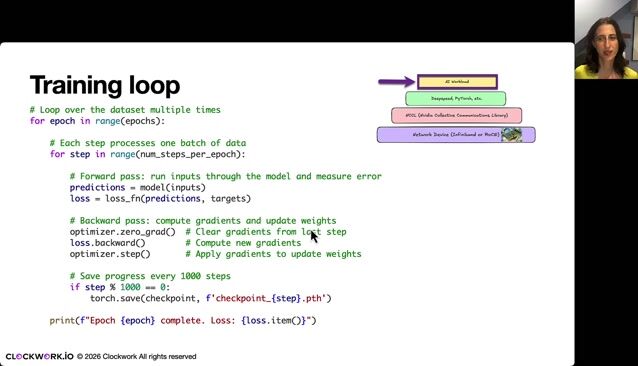
The successful candidate will take end-to-end ownership of the GPU infrastructure function, developing the frameworks and automation used to validate, benchmark, and certify large-scale GPU clusters. Combining hands-on engineering with technical leadership, they will build deployment and testing tooling, establish infrastructure standards, shape technical strategy alongside the founders, and ultimately build and lead the team responsible for the function., * Design and run cluster validation and certification: performance benchmarks, interconnect testing (NCCL, InfiniBand/RoCE), thermal and power verification, availability monitoring against SLAs.
- Build automation for cluster deployment, health checks, and continuous testing so certification scales without headcount scaling with it.
- Set the technical standards for what “deliverable compute” means: node configs, network topologies, storage, cooling envelopes.
- Work directly with capacity providers (neoclouds, data centre operators) during onboarding, from site walkthroughs to acceptance testing.
- Feed what you learn on the ground back into our contract specs, index methodology, and product roadmap.
- Hire and lead the infrastructure engineering team as we grow.
Requirements
- Experience deploying GPU clusters at varying scales, from smaller node deployments to environments with hundreds or thousands of GPUs, across both air-cooled and liquid-cooled infrastructure. DLC experience is highly advantageous.
- Strong experience troubleshooting complex infrastructure issues, including cabling and topology errors, firmware mismatches, failing optics, thermal throttling, and production performance challenges.
- Experience automating infrastructure-as-code deployments, monitoring and alerting stacks, and hardware acceptance and regression testing.
- Deep familiarity with the NVIDIA technology stack, including HGX platforms, NVLink/NVSwitch, CUDA-level debugging, and NCCL performance tuning.
- Strong leadership skills with the ability to set technical direction, solve complex problems, and guide engineering teams.
- Excellent communication skills with the ability to engage effectively with non-infrastructure stakeholders, including traders, lawyers, capacity providers, and regulators.
Apply for this position
This job is hosted externally. Click below to view the full posting and apply.
Prepare application
- Draft this with your agent
- Open in Claude
- Open in ChatGPT
Good distractions
Talks and stories from around this role — technically off-topic, practically not.
Moments
Explore playlistsVideos
See allRelated articles
See all
Best US AI Conferences for CTOs in 2026: Build vs. Buy, Vendor Evaluation, and Peer Intelligence
7 Cloud Computing Trends Coming in 2025 for Developers
Dev Digest 157: CUDA in Python, Gemini Code Assist and Back-dooring LLMs
Dev Digest 120 - Apple and peers