
BB
Benedikt Bischof
Making Data Warehouses Fast: A Developer’s Story
about 4 years ago
Build scalable, production-grade ETL/ELT pipelines using Databricks (PySpark, Spark SQL, Delta Live Tables, Workflows).
Ingest structured, semi-structured, and streaming data into Bronze, Silver, and Gold layers.
Develop optimized transformations, data quality rules, and reusable framework components.
Implement best practices for job orchestration, monitoring, alerting, and automation.
Hands-on experience: Spark, Delta Lake, Workflows, Unity Catalog.
Strong SQL programming and performance tuning skills.
Experience with cloud environments (AWS/Azure/GCP).
Experience with modern data lakehouse concepts and distributed systems.
Strong understanding of Lakeflow Connect, LSDP/Lakehouse, Medallion Architecture, Data Validations, Genie, and Agent Bricks/RAG use cases.
Should be able to explain these concepts using real project examples and architecture decisions.
Requirements
Strong Python (PySpark) and SQL programming
Databricks - Spark, Delta Lake, Workflows, Unity Catalog
ETL/ELT pipeline development - Medallion Architecture (Bronze/Silver/Gold)
Delta Live Tables, Auto-Loader, Structured Streaming
Data modeling - dimensional (star/snowflake), normalization/denormalization
CI/CD, Git, job orchestration
Cloud experience - AWS, Azure, or GCP
7-10+ years in data engineering
Nice-to-Have Skills
Lakeflow Connect, LSDP/Lakehouse, Genie, Agent Bricks/RAG use cases
Data governance, metadata management, Unity Catalog advanced features
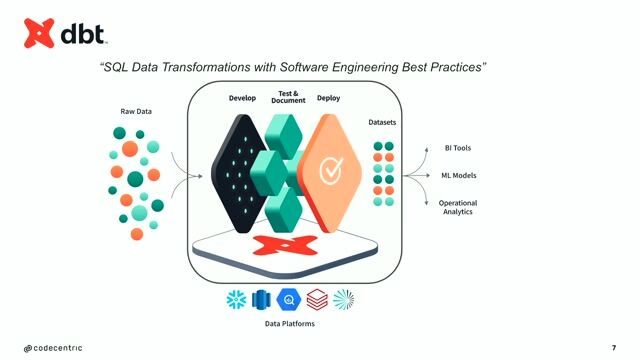
Airflow, dbt, or similar orchestration tools
Data security, compliance, and access models
Cost optimization and performance tuning in cloud environments
Corporate/enterprise data warehousing background
DATAECONOMY is one of the fastest-growing Data & Analytics company with global presence. We are well-differentiated and are known for our Thought leadership, out-of-the-box products, cutting-edge solutions, accelerators, innovative use cases, and cost-effective service offerings. We offer products and solutions in Cloud, Data Engineering, Data Governance, AI/ML, DevOps and Blockchain to large corporates across the globe. Strategic Partners with AWS, Collibra, cloudera, neo4j, DataRobot, Global IDs, tableau, MuleSoft and Talend., DATAECONOMY
This job is hosted externally. Click below to view the full posting and apply.
Talks and stories from around this role — technically off-topic, practically not.
2:15 min
 Sandhya Menon · World Congress 2026 Europe
2:57 min
Sandhya Menon · World Congress 2026 Europe
4:32 min
6:21 min
3:37 min
3:05 min
 Joy · World Congress 2024