





CH
Chris Heilmann
Coffee with Developers - Maria Apazoglou - Making AI understandable for all in production
about 2 years ago
Sephora is looking for engineers to help build the next generation of its Retail and Omnichannel Analytics platform. These roles combine hands-on engineering, technical leadership, and architecture across the complete analytics lifecycle, including source-system integration, ingestion, transformation, governance, semantic modeling, reporting, self-service analytics, and AI-enabled data products.
The engineers will establish scalable Databricks standards and reusable frameworks, build modern Lakehouse solutions, and enable capabilities such as Databricks Genie. Strong candidates will have previously led Databricks platform modernization, analytics transformation, or enterprise data-platform initiatives and will be comfortable combining architectural leadership with hands-on delivery
Day-to-Day Responsibilities:
Design and build scalable ingestion, transformation, and data-product frameworks using Databricks and Azure technologies.
Establish and drive Databricks best practices for Bronze, Silver, and Gold architecture, governance, performance, data quality, and operational excellence.
Build batch, near real-time, and streaming pipelines using Databricks, Spark/PySpark, Delta Lake, and Azure Data Factory.
Deliver end-to-end Retail and Omnichannel Analytics data products, from source-system ingestion through reporting and AI-enabled solutions.
Develop trusted analytical datasets, dimensional and semantic models, and governed consumption layers.
Enable self-service analytics through Databricks Genie and reusable, business-ready data products.
Implement governance, security, data quality, lineage, monitoring, and observability practices.
Lead proofs of concept and evaluate emerging capabilities across the Databricks ecosystem.
Define AI SDLC, AI-assisted development, AI-agent, and engineering-automation patterns.
Partner with engineering, analytics, product, and business teams while mentoring engineers and promoting standards across multiple teams.
We are a company committed to creating diverse and inclusive environments where people can bring their full, authentic selves to work every day. We are an equal opportunity/affirmative action employer that believes everyone matters. Qualified candidates will receive consideration for employment regardless of their race, color, ethnicity, religion, sex (including pregnancy), sexual orientation, gender identity and expression, marital status, national origin, ancestry, genetic factors, age, disability, protected veteran status, military or uniformed service member status, or any other status or characteristic protected by applicable laws, regulations, and ordinances. If you need assistance and/or a reasonable accommodation due to a disability during the application or recruiting process, please send a request to HR@insightglobal.com.To learn more about how we collect, keep, and process your private information, please review Insight Global’s Workforce Privacy Policy: https://insightglobal.com/workforce-privacy-policy/.
7+ years of Data Engineering experience.
Strong hands-on Databricks experience within enterprise production environments.
Advanced expertise in Python, SQL, Scala, Spark/PySpark, and Delta Lake.
Strong experience with Azure Data Factory, Azure DevOps, Git, CI/CD pipelines, and release management.
Experience building Lakehouse architectures and implementing Medallion Architecture using Bronze, Silver, and Gold layers.
Strong experience designing ETL/ELT processes, data integrations, and scalable batch, near real-time, and streaming pipelines.
Experience creating analytical, dimensional, and semantic data models.
Experience delivering end-to-end analytics solutions, from source-system integration and ingestion through transformation, governance, semantic modeling, reporting, and AI-enabled solutions.
Strong understanding of data governance, security, data quality, lineage, observability, monitoring, and performance optimization.
Experience establishing reusable frameworks, platform standards, and engineering best practices adopted across multiple teams.
Ability to combine architecture and technical leadership with hands-on engineering delivery.
Strong communication skills with the ability to lead technical discussions and mentor engineers. Nice to Haves:
Experience with Unity Catalog, LakeFlow, Delta Live Tables, Databricks SQL, Databricks Genie, and Databricks Workflows.
Experience enabling self-service analytics and data democratization through semantic models and reusable, business-ready data products.
Experience implementing AI-assisted development, AI SDLC practices, GenAI-enabled engineering workflows, and AI agents.
Experience designing automation or engineering accelerators that improve developer productivity.
Experience leading Databricks platform modernization, analytics transformation initiatives, and technical proof-of-concepts.
Experience in Retail and Omnichannel Analytics, Merchandising, Inventory, Supply Chain, Store Operations, Customer Analytics, or Digital Commerce.
Experience integrating REST APIs and source systems into modern data platforms
This job is hosted externally. Click below to view the full posting and apply.
Talks and stories from around this role — technically off-topic, practically not.
6:21 min
4:32 min
2:27 min
 Viktoria Semaan · World Congress 2026 Europe
3:03 min
2:50 min
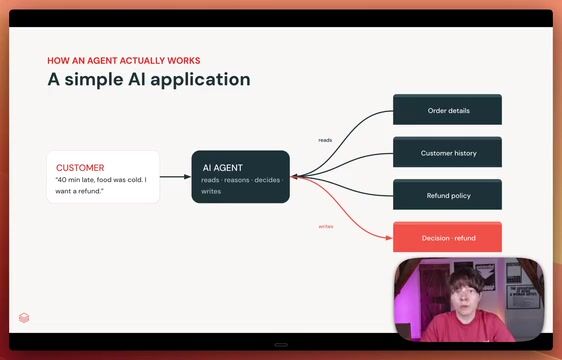
Viktoria Semaan · World Congress 2026 Europe
3:37 min




