

IK
Igor Khokhriakov
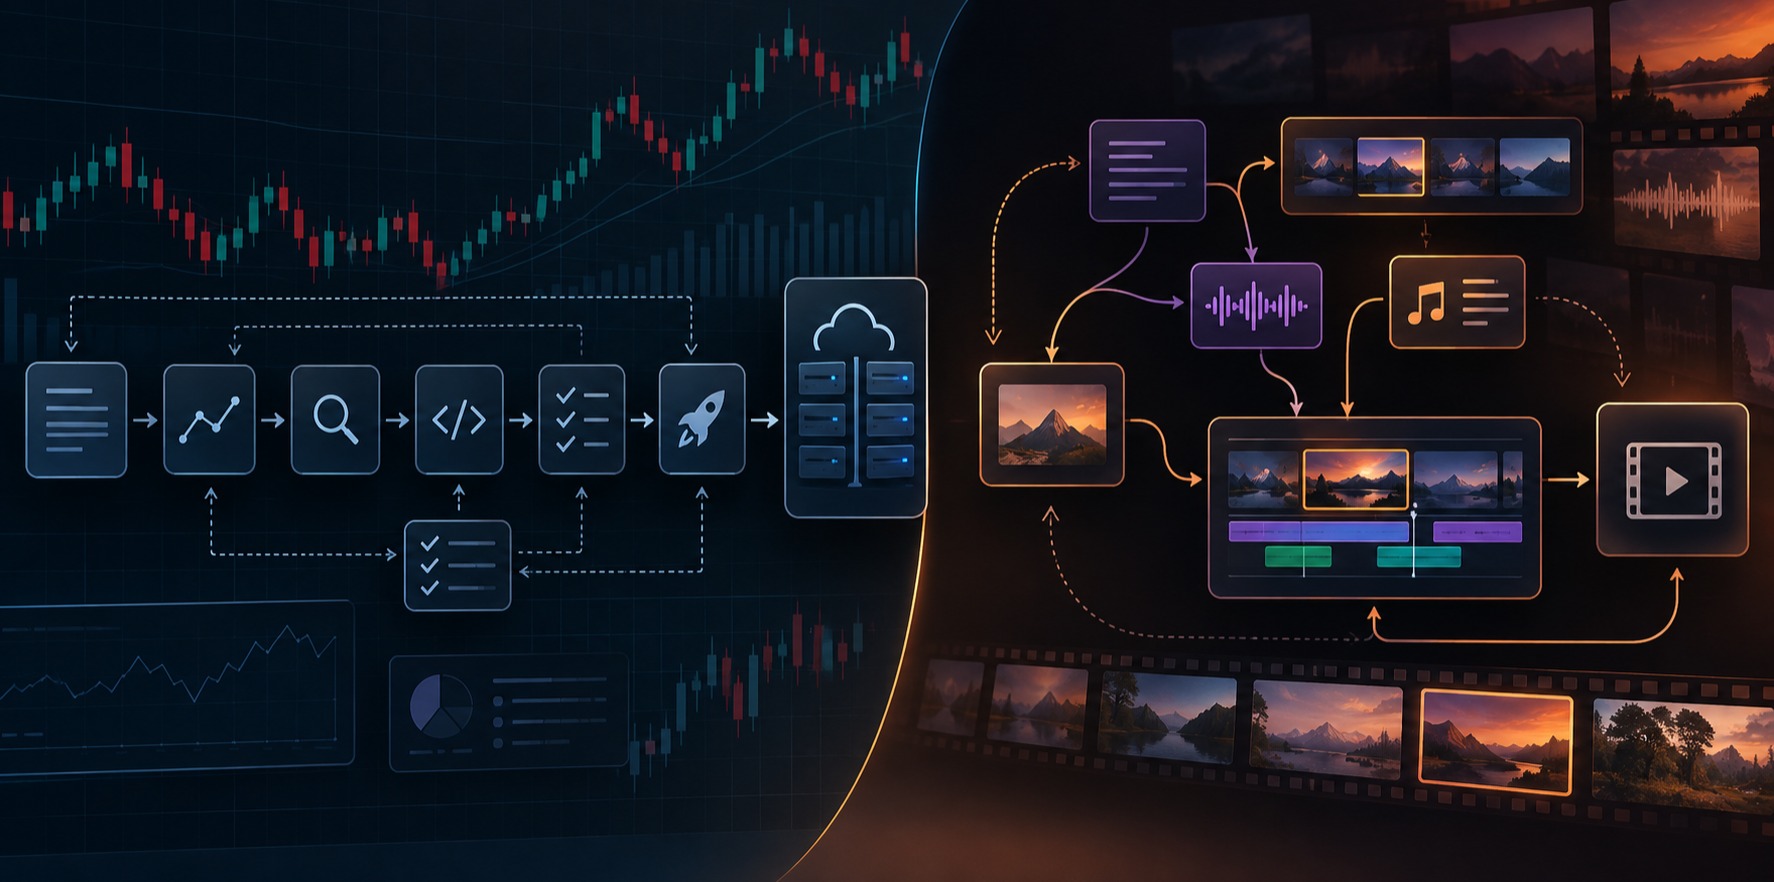
I Gave a Video Editor More Autonomy Than a Trading Bot. On Purpose.
1 day ago
United States, California, San Francisco 650 Townsend Street (Show on map) Sep 02, 2026 About Scale AI
At Scale, our mission is to develop reliable AI systems for the world’s most important decisions. Our products provide the high-quality data and full-stack technologies that power the world’s leading models, and help enterprises and governments build, deploy, and oversee AI applications that deliver real impact.
Scale Frontier Data is the organization behind the training and evaluation data that frontier labs depend on. We build the systems, tooling, and expert workflows that turn hard human expertise into signals that models can learn from, across reasoning, coding, agentic tool use, and domain expertise.
Reinforcement learning environments are now the center of gravity for that work: the difference between a model that demos well and a model that reliably completes long-horizon work is almost always the quality of the environments and reward signals it was trained against.
Responsibilities
As a Staff Software Engineer, RL Environments, you’ll own the technical foundation for how Scale builds, runs, verifies, and delivers RL environments at scale. An RL environment is a real piece of software: a containerized world with real dependencies, real state, real tools, and a grader that has to be correct even when the agent is creative about breaking it. Building one is a full-stack engineering problem. Building thousands of them reproducibly, cheaply, with trustworthy reward signals and throughput measured in millions of rollouts is a systems problem that very few people have solved.
You’ll work on both. You’ll design the platform: sandboxed execution, environment packaging and versioning, rollout orchestration, trajectory capture, verifier frameworks, and the authoring surfaces that let engineers and domain experts produce environments without reinventing infrastructure each time. And you’ll go deep on the environments themselves by instrumenting real applications, designing task suites that expose specific capability gaps, and building graders that hold up under adversarial optimization. This is a hands-on engineering role. You’ll set technical direction across multiple teams, and you’ll still be the person who writes the hard part., Compensation packages at Scale for eligible roles include base salary, equity, and benefits. The range displayed on each job posting reflects the minimum and maximum target for new hire salaries for the position and may be inclusive of several career levels at Scale; it will be determined during the interview process based on work location and additional factors, including job-related skills, experience, qualifications, interview performance, and relevant education or training. Scale employees in eligible roles are also granted equity based compensation, subject to Board of Director approval. Your recruiter can share more about the specific salary range for your preferred location during the hiring process, and confirm whether the hired role will be eligible for equity grant. You’ll also receive benefits including, but not limited to: comprehensive health, dental and vision coverage, retirement benefits, a learning and development stipend, and generous PTO. Additionally, this role may be eligible for additional benefits such as a commuter stipend. Please reference the job posting’s subtitle for where this position will be located. For pay transparency purposes, the base salary range for this full-time position in the locations of San Francisco, New York, Seattle is: $252,000 - $315,000 USD
PLEASE NOTE:Our policy requires a 90-day waiting period before reconsidering candidates for the same role. This allows us to ensure a fair and thorough evaluation of all applicants.
Preferred Qualifications RL & Post-Training
Systems & Infrastructure
Ways of Working
At Scale, our mission is to develop reliable AI systems for the world’s most important decisions. Our products provide the high-quality data and full-stack technologies that power the world’s leading models, and help enterprises and governments build, deploy, and oversee AI applications that deliver real impact. We work closely with industry leaders like Meta, Ernst & Young, Mayo Clinic, Time Inc., the Government of Qatar, and U.S. government agencies including the Army and Air Force. We are expanding our team to accelerate the development of AI applications.
This job is hosted externally. Click below to view the full posting and apply.
Talks and stories from around this role — technically off-topic, practically not.
3:09 min
2:07 min
 Oliver Seitz · World Congress 2025
2:32 min
1:21 min
2:14 min
2:34 min
 Manuel de la Peña · World Congress 2026 Europe




