WeAreDevelopers LIVE Oct 2, 2024

DevOps for AI: running LLMs in production with Kubernetes and KubeFlow

Aarno Aukia

Are silent API updates secretly breaking your production AI? Regain control by self-hosting and autoscaling LLMs natively with Kubernetes, KServe, and proven DevOps principles.

Pause
Mute Enter Fullscreen
#1 about 5 min

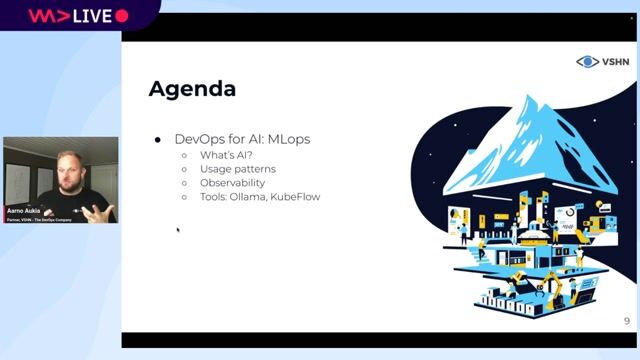
Introduction to DevOps for AI and MLOps

Applying traditional automation principles to machine learning operations minimizes deployment risk and maximizes developer productivity.

#2 about 4 min

Evolution of machine learning and generative AI

Scaling deep learning algorithms with hardware acceleration enables modern systems to reliably generate novel content.

#3 about 4 min

Understanding tokenization and probability in large language models

Analyzing the tokenization layer and statistical rendering engines of language models explains why their outputs remain explicitly non-deterministic.

#4 about 5 min

Prompt engineering techniques and security vulnerabilities

Providing targeted instructions and context eliminates unnecessary model complications but introduces potential security risks like malicious prompt injections.

#5 about 4 min

Enhancing models with retrieval augmented generation and fine-tuning

Indexing proprietary documentation for retrieval prevents model hallucinations, while permanent fine-tuning adapts generic models to domain-specific terminology.

#6 about 6 min

Consuming cloud-hosted models through black box APIs

Relying on commercial algorithms requires robust observability and failover mechanisms to securely handle unpredictable service updates.

#7 about 2 min

Running local open source models using Ollama

Leveraging standardized containerization engines allows developers to seamlessly download and execute language models offline natively on local hardware.

#8 about 4 min

Serving production machine learning workloads with KubeFlow and KServe

Implementing specialized orchestration operators standardizes the machine learning lifecycle to serve scalable inference workloads flawlessly.

#9 about 4 min

Configuring horizontal autoscaling for language models with KServe

Defining orchestration resource limitations dynamically scales active container instances while effortlessly capturing diagnostic metrics for visualization.

#10 about 1 min

Choosing between standalone hardware and highly scalable infrastructure

Organizations must evaluate the reduced complexity of standalone hardware runtimes against the absolute operational maturity demanded by auto-scaling architectures.

Matching moments

4:15 min

Introduction to artificial intelligence driven development

Natalie Pistunovich · LIVE

2:08 min

Essential engineering roles in the generative AI space

Mary Grygleski Mary Grygleski · LIVE

5:28 min

Defining MLOps and its role in production systems

Hauke Brammer · World Congress 2023

2:14 min

Differences between traditional MLOps and GenAIOps

Maxim Salnikov Maxim Salnikov · World Congress 2025

7:28 min

Accelerating product features using generative large language models

David Singleton David Singleton +1 · Coffee With Developers

4:57 min

Centralizing LLMOps workflows within Azure AI Foundry

Maxim Salnikov Maxim Salnikov · LIVE

Upcoming sessions on this topic

Open session

World Congress 2026 North America

September 24, 2026 · 17:30–18:00

Stage 6

No Single Model to Rule Them All: Building Resilient AI Agents Across Open & Closed LLMs

Emmanuel Acheampong

Senior Manager Developer Relations at Crusoe AI

Emmanuel Acheampong
Open session

World Congress 2026 North America

September 25, 2026 · 13:30–14:00

Mainstage

A Hands-On Developer Guide to Inference Engineering

Ankit Patel, Philip Kiely

Ankit Patel
Philip Kiely
Open session

World Congress 2026 North America

September 24, 2026 · 16:10–16:40

Stage 9

Fast, Cheap, and Accurate: Optimizing LLM Inference with vLLM and Quantization

Legare Kerrison, Cedric Clyburn

Legare Kerrison
Cedric Clyburn
Open session

World Congress 2026 North America

September 24, 2026 · 14:10–14:40

Stage 1

Anatomy of an AI Request: Where Latency and Cost Are Really Born

Dan Fu

VP of Kernels at Together AI

Dan Fu
Open session

World Congress 2026 North America

September 25, 2026 · 11:40–12:10

Stage 9

You Can’t Re-Run Sunlight: Designing ML Data Architectures for Physical AI

An Phan

Senior Data Infrastructure Engineer @ Hippo Harvest

An Phan
Open session

World Congress 2026 North America

September 23, 2026 · 10:45–12:45

Stage 10

Agents That Own Their Inference: Building Production AI Agents on Dedicated GPUs

Duan Lightfoot

Sr. AI Engineer, Akamai

Duan Lightfoot