

CH
Chris Heilmann
How to scrape modern websites to feed AI agents
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
Feeding raw HTML to your LLM guarantees garbage outputs. Learn to bypass modern bot blockers to extract clean data. Transform your AI into a web-integrated operator.
Matching moments
2:21 min
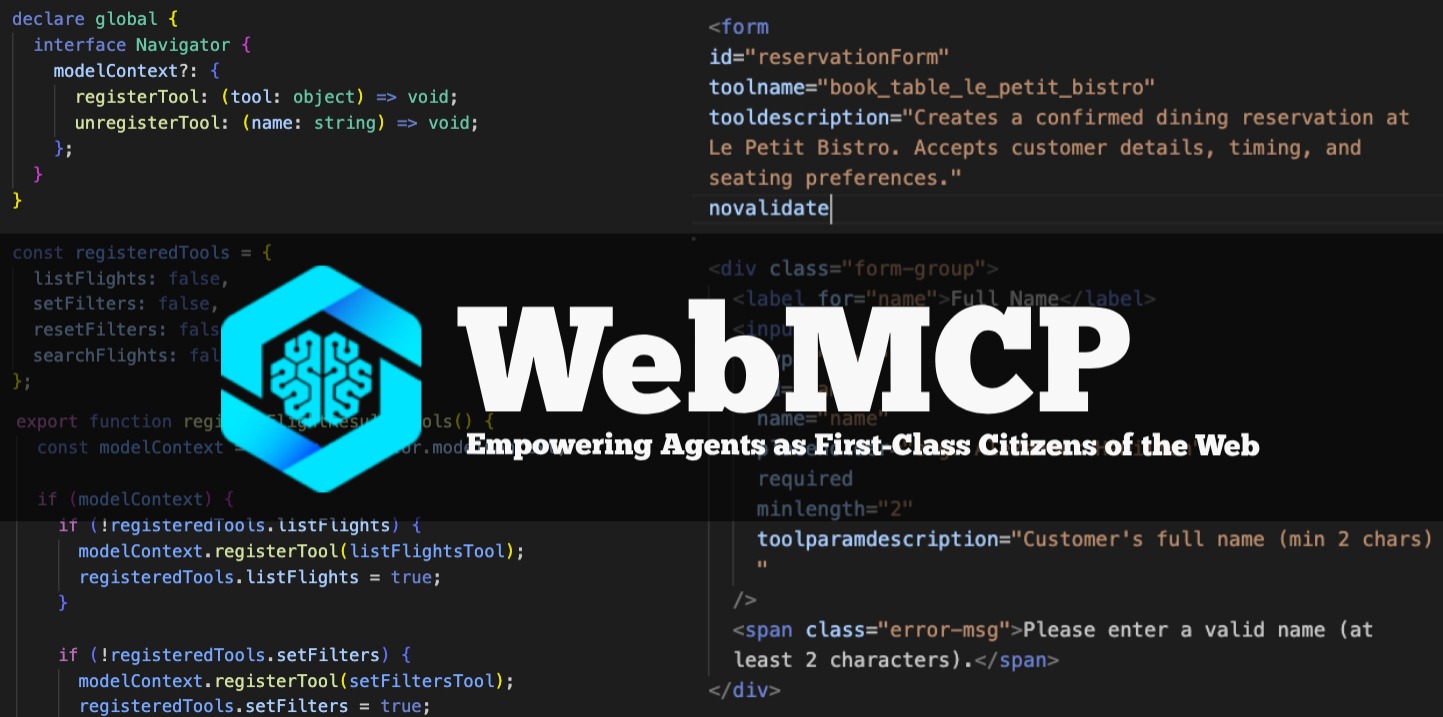
Core concepts and mechanics behind Web MCP
Alex Nahas · Coffee With Developers
4:20 min
Automating tasks securely through agentic browser protocols
 Christian Liebel · World Congress 2026 Europe
5:54 min
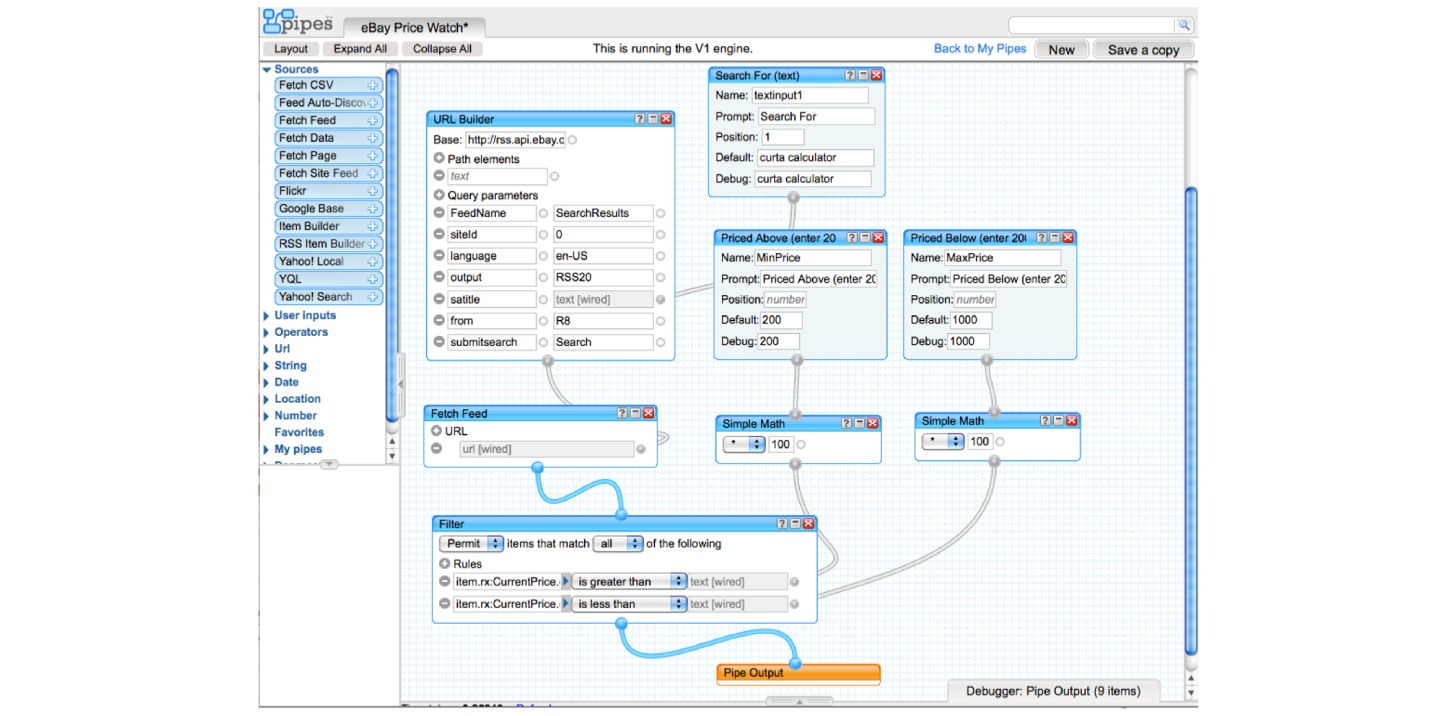
The technical evolution of modern web scraping infrastructure
 Chris Heilmann +4 · LIVE
3:35 min
Impact of AI data scraping on open web content
Léonie Watson · A11y + AI
5:54 min
Standardizing agent interactions with the Web MCP proposal
Chris Heilmann +2 · LIVE
1:48 min
Exploring AI integrations in modern agile development workflows
 Markus Walker · World Congress 2023
More from World Congress 2025
Related videos
Related articles
CH
Chris Heilmann
MH
Michael Hunger
CH
Chris Heilmann

DC
Daniel Cranney

From learning to earning
Jobs that call for the skills explored in this talk.
22 days ago
Senior AI Developer
PwC
United States
Expert
Remote
Docker
Github
Fastapi
6 days ago
•
Verified
AI Software Engineer (Germany)
Sunhat
Berlin, Germany
Expert
€70k–100k
Remote
REST
TypeScript
AI Frameworks
about 1 month ago
•
Verified
Senior AI/ML Engineer
PagerDuty
Lisbon, Portugal
Expert
Remote
AI Frameworks
AI-assisted coding tools
about 1 month ago
•
Verified
LLM Training Engineer
Sciforium
San Francisco, United States
Expert
$155k–220k
Python
about 1 month ago
•
Verified
Staff Software Engineer, Agentic Platform
Docker, Inc.
Seattle, United States
Expert
Remote
Cloud (AWS/Google/Azure)
about 1 month ago
•
Verified
Software Engineer, Fullstack
Sciforium
San Francisco, United States
Expert
$165k–210k
Python