
BB
Benedikt Bischof
Evaluating AI models for code comprehension
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
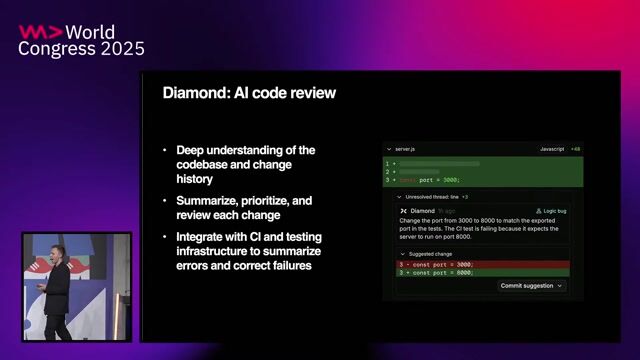
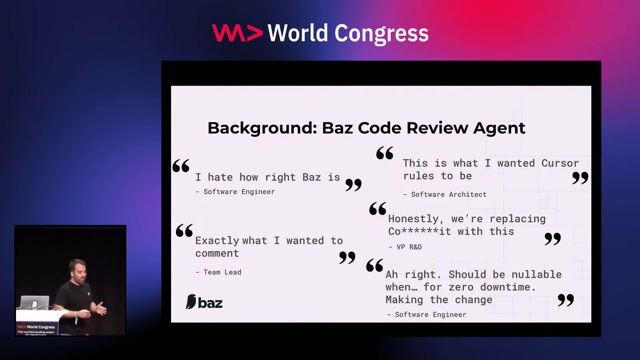
Are noisy AI code reviews eroding your engineers' trust? Discover the evaluation strategies that prove why Claude 3.7 Sonnet outperforms Gemini and GPT-4o for automated pull requests.
Matching moments
2:40 min
Reviewing live performance of self-correcting AI engineering agents
 Ingo Eichhorst · World Congress 2026 Europe
3:01 min
Balancing artificial intelligence tools with foundational software engineering skills
Tim Ruscica · Coffee With Developers
3:22 min
Evaluating advanced artificial intelligence platforms for daily recruitment
 Rudi Bauer +1 · Cappuccino with HR
1:56 min
Analyzing cloud-based AI code completion architectures
 Daniel Savenkov · World Congress 2024
1:49 min
Using a council of adversarial agents for code review
 Milin Desai +1 · World Congress 2026 Europe
2:33 min
Evaluating AI comprehension and output quality
Perf + AI
More from World Congress 2025
Related videos
Related articles

DC
Daniel Cranney
CH
Chris Heilmann
AS
Alan Smithee
From learning to earning
Jobs that call for the skills explored in this talk.
2 months ago
•
Verified
AI Software Engineer (Germany)
Sunhat
Berlin, Germany
Expert
€70k–100k
Remote
REST
TypeScript
AI Frameworks
about 1 month ago
•
Verified
Senior AI/ML Engineer
PagerDuty
Lisbon, Portugal
Expert
Remote
AI Frameworks
AI-assisted coding tools
about 1 month ago
•
Verified
LLM Training Engineer

Sciforium
San Francisco, United States
Expert
$155k–220k
Python
16 days ago
Senior AI Developer
PwC
United States
Expert
Remote
Docker
Github
Fastapi
15 days ago
Principal Software Engineer, AI Inference Runtime

ARM
Seattle, WA, United States
Expert
$262k
Compilers
Low Latency
Concurrency
about 2 months ago
MLOps AI Engineer

TeamViewer Germany GmbH,
Austin, TX, United States
Expert
Caching
Routing
Standard Sql