
WeAreDevelopers LIVE
•
Nov 30, 2020
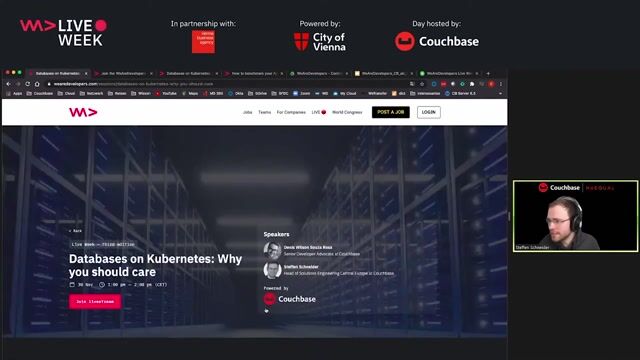
Databases on Kubernetes: Why you should care
Denis Wilson Souza Rosa , Steffen Schneider
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
Still afraid to run stateful applications in containers? Discover how Kubernetes Operators bring the hands-off convenience of a managed DBaaS straight into your own cluster.
Matching moments
1:58 min
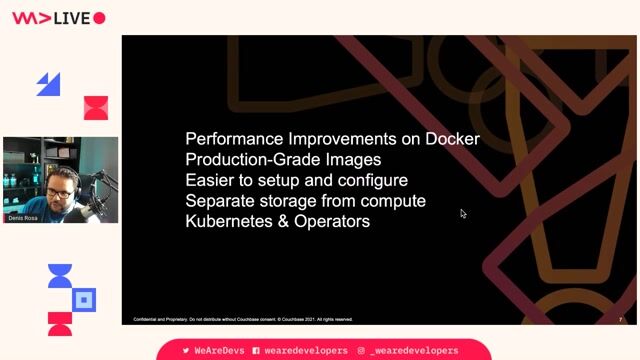
Modern improvements driving database adoption in Kubernetes
Denis Souza Rosa · LIVE
2:49 min
Deploying mission-critical databases within container infrastructures
 Wei Hu · World Congress 2022
2:49 min
Evolution of stateful applications in container environments
Denis Souza Rosa · LIVE
4:54 min
Managing heterogeneous deployment lifecycles via Kubernetes operators
Wei Hu · World Congress 2022
3:39 min
Comparing managed database services against self-hosted Kubernetes operators
Denis Souza Rosa · LIVE
5:12 min
Extending Kubernetes functionality with custom resource definitions
Denis Souza Rosa · LIVE
More from WeAreDevelopers LIVE
Related videos
Related articles
BB
Benedikt Bischof

DC
Daniel Cranney

AA
Ali Alp
From learning to earning
Jobs that call for the skills explored in this talk.
27 days ago
•
Verified
Senior Software Engineer, Infrastructure

Docker, Inc.
Seattle, United States
Expert
Remote
Go
Kubernetes
27 days ago
•
Verified
Principal Backend Engineer, Hub
Docker, Inc.
United States
Expert
Remote
Go
Kubernetes
Cloud (AWS/Google/Azure)
27 days ago
•
Verified
Staff Software Engineer, Infrastructure
Docker, Inc.
Expert
Remote
Go
Kubernetes
27 days ago
•
Verified
Senior Software Engineer, Billing
Docker, Inc.
Seattle, United States
Expert
Remote
Terraform
Kubernetes
Amazon Web Services…
about 2 months ago
Software Engineer, Infrastructure Platform
Docker, Inc.
Madrid, Spain
€72k–123k
Remote
Istio
Linux
Docker
12 days ago
Cloud Engineer (German)

Stackit
Barcelona, Spain
Git
Okta
OAuth