
CH
Chris Heilmann
Performant Architecture for a Fast Gen AI User Experience
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
Multi-second latency ruins real-time voice apps. Stop relying on naive batch processing. Discover how semantic chunking and edge models combine to deliver instantaneous generative AI experiences.
Matching moments
1:22 min
Leveraging the comprehensive generative artificial intelligence stack
 Duan Lightfoot · World Congress 2024
1:10 min
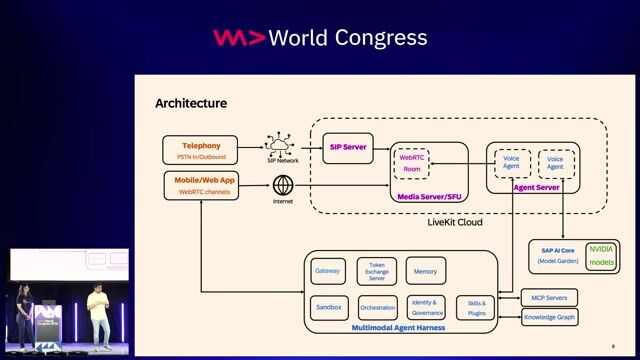
Architecting a web real-time communication stack for agents
 Nathaniel Okenwa · World Congress 2025
5:28 min
Integrating OpenAI for real-time streaming responses
 Chris Heilmann +3 · LIVE
4:03 min
Enhancing conversational output via generative AI models
Xavier Portilla Edo · LIVE
4:16 min
Addressing latency and architecture in voice agents
Chris Heilmann +2 · LIVE
2:14 min
Optimizing modular voice AI pipelines for speech processing
 Anahita Havewala +1 · World Congress 2026 North America
More from World Congress 2024
Related videos
Related articles
BB
Benedikt Bischof

DC
Daniel Cranney
MH
Michael Hunger
N
Neo4j
From learning to earning
Jobs that call for the skills explored in this talk.
2 months ago
Software Engineer - Video

Twilio
Austin, TX, United States
Experienced
$138k–203k
Remote
NoSQL
Nagios
Twilio
11 days ago
•
Verified
AI Software Engineer (Germany)
Sunhat
Berlin, Germany
Expert
€70k–100k
Remote
REST
TypeScript
AI Frameworks
27 days ago
Senior AI Developer
PwC
United States
Expert
Remote
Docker
Github
Fastapi
about 2 months ago
Machine Learning Engineer
Twilio
United States
Experienced
Remote
Spacy
Pytorch
Chatbots
about 2 months ago
•
Verified
Software Engineer, Fullstack
Sciforium
San Francisco, United States
Expert
$165k–210k
Python
5 days ago
Engineering Manager, Google Cloud AI/ML
PwC
Portland, OR, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI