Senior Software Engineer, Distributed Systems Engineer - DGX Cloud

NVIDIA Corporation
Santa Clara, CA, United States
4 days ago
Apply on www.jofdav.com
Prepare application

Role details

Contract type
Permanent contract
Employment type
Full-time (> 32 hours)
Experience level
Expert
Experience required
5 years minimum
Compensation
$164,500.0 - $255,275.0
Working hours
Regular working hours
Job source

Tech stack

Application Programming Interfaces (APIs) Artificial Intelligence Cloud Computing Computer Clusters Computer Graphics Custom Software Data Structures Distributed Systems Video Game Development Python (Programming Language) Software Engineering Data Streaming
+7 more
System Programming AI Infrastructure Graphics Processing Unit (GPU) Deep Learning Kubernetes Information Technology Slurm

Job description

NVIDIA is hiring experienced software engineers with kubernetes experience to help scale up its AI Infrastructure. We expect you to have significant software engineering experience with kubernetes including cluster operations, operator development, node health monitoring and working with GPU resource scheduling. We welcome out-of-the-box thinkers who can provide new ideas with strong execution bias. Expect to be constantly challenged, improving, and evolving for the better. You will help advance NVIDIA’s capacity to build and deploy leading infrastructure solutions for a broad range of AI-based applications. If you’re creative, passionate about kubernetes and GPUs, and love having fun, please apply today!

For two decades, we have pioneered visual computing, the art and science of computer graphics. With the invention of the GPU - the engine of modern visual computing - the field has expanded to encompass video games, movie production, product design, medical diagnosis and scientific research. Today, we stand at the beginning of the next era, the AI computing era, ignited by a new computing model, GPU deep learning.

What you will be doing:

  • You will be part of an DGX Cloud team responsible for production systems that enable large scalable GPU clusters to be used for a variety of AI workloads. This includes working on custom software related to scheduling GPU resources on kubernetes.
  • Implementing monitoring and health management capabilities that enable industry leading reliability, availability, and scalability of GPU assets. You will be harnessing multiple data streams, ranging from GPU hardware diagnostics to cluster and network telemetry.
  • Working with teams across NVIDIA to ensure production AI clusters run reliability and consistently with maximum performance. Evaluating system failures and improving services based on a well-defined incident management process.

Requirements

  • Direct experience in a software engineering role within a highly technical organization with demonstrable impact from your work. Software development experience with kubernetes APIs and frameworks not just operating a cluster.
  • Highly motivated with strong communication skills, you can work successfully with multi-functional teams, principles, and architects and coordinate effectively across organizational boundaries and geographies.
  • 5+ years in similar role and experience on large-scale production systems. Experience with common software engineering principles, tools and techniques.
  • You possess a BS in Computer Science, Engineering, Physics, Mathematics or a comparable Degree or equivalent experience.
  • Technical knowledge, including a systems programming language (Go, Python) and a solid understanding of data structures and algorithms.

Ways to stand out from the crowd:

  • Technical competency in managing and automating large-scale distributed systems independent of cloud providers. Advanced hands-on experience and deep understanding of cluster management systems (Kubernetes, Slurm, Bright Cluster Manager)
  • Proven operational excellence in maintaining reliable and performant AI infrastructure.

Benefits & conditions

NVIDIA is widely considered to be one of the technology world’s most desirable employers. We have some of the most forward-thinking and hardworking people on the planet working for us. If you are creative and autonomous, we want to hear from you!

Your base salary will be determined based on your location, experience, and the pay of employees in similar positions. The base salary range is 152,000 USD - 241,500 USD for Level 3, and 184,000 USD - 287,500 USD for Level 4.

You will also be eligible for equity and benefits ., $164,500.00 - $255,275.00 per year

Apply for this position

This job is hosted externally. Click below to view the full posting and apply.

Apply on www.jofdav.com
Prepare application

Good distractions

Talks and stories from around this role — technically off-topic, practically not.

2:47 min

Contrasting classical machine learning with deep learning approaches

Adrian Spataru +1 · LIVE

1:15 min

Deploying local container pods to Kubernetes clusters

Stevan Le Meur Stevan Le Meur · World Congress 2024

2:22 min

Infrastructure barriers and compliance risks in research

Jeremy Murray Jeremy Murray · World Congress 2026 Europe

2:33 min

Architecting CUDA and the AI software stack

Michael Kagan Michael Kagan +1 · World Congress 2026 Europe

33 sec

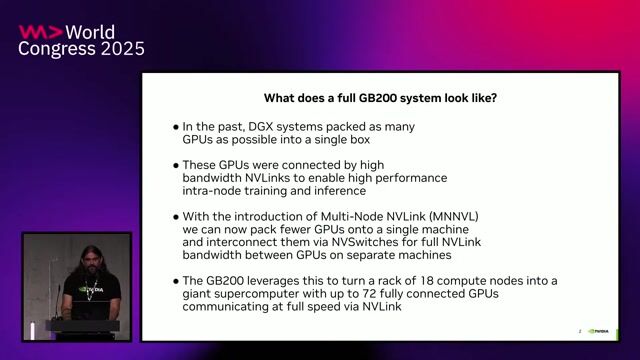
Supporting NVIDIA GB200 GPUs on Kubernetes

Kevin Klues Kevin Klues · World Congress 2025

1:25 min

Distinguishing artificial intelligence from deep learning

Sam Witteveen · Coffee With Developers

Videos

See all

Related articles

See all
