


DA
Dr. Andy R. Terrel - NVIDIA
CUDA Python: GPU programming for the modern developer
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
Achieve speed-of-light C++ performance without ever leaving Python. Learn how modern CUDA tooling unlocks massive multi-GPU acceleration and instant 10x speedups for your heaviest data workloads.
Matching moments
4:37 min
Simplifying parallel programming with the CUDA ecosystem
 Paul Graham · LIVE
3:32 min
Evolution of general purpose GPU computing and Python
Paul Graham · World Congress 2025
2:27 min
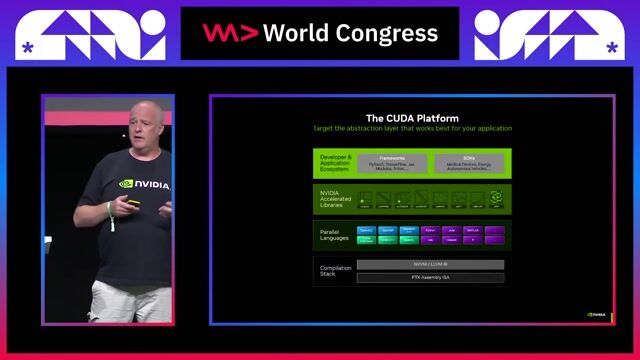
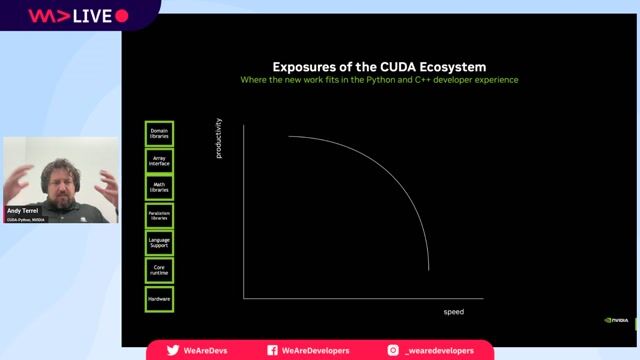
Exploring the CUDA ecosystem and levels of abstraction
Paul Graham · World Congress 2025
2:18 min
Bridging the productivity and speed gap in Python
Andy Terrel · LIVE
1:37 min
Accelerating compute with focused developer tools
 Julia Koch +1 · World Congress 2026 Europe
2:31 min
Defining CUDA as a comprehensive GPU platform
Stephen Jones · Coffee With Developers
More from World Congress 2026 Europe
Related videos
Related articles

DC
Daniel Cranney

BB
Benedikt Bischof
BB
Benedikt Bischof

From learning to earning
Jobs that call for the skills explored in this talk.
about 1 month ago
•
Verified
GPU Cluster Engineer, Systems & Platform

Sciforium
San Francisco, United States
Expert
$150k–220k
Kubernetes
about 1 month ago
•
Verified
GPU Kernel Engineer
Sciforium
San Francisco, United States
Expert
$190k–250k
PyTorch
15 days ago
Principal Software Engineer, AI Compute Infrastructure

ARM
Seattle, WA, United States
Expert
$262k
Linux
Grafana
Pytorch
about 1 month ago
•
Verified
Lead Software Engineer, Model Serving Platform
Sciforium
San Francisco, United States
Expert
$230k–300k
Python
about 1 month ago
•
Verified
Distributed Training and Inference Engineer
Sciforium
San Francisco, United States
Expert
$190k–250k
Linux kernel
15 days ago
Principal Software Engineer, AI Inference Runtime
ARM
Seattle, WA, United States
Expert
$262k
Compilers
Low Latency
Concurrency