





How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
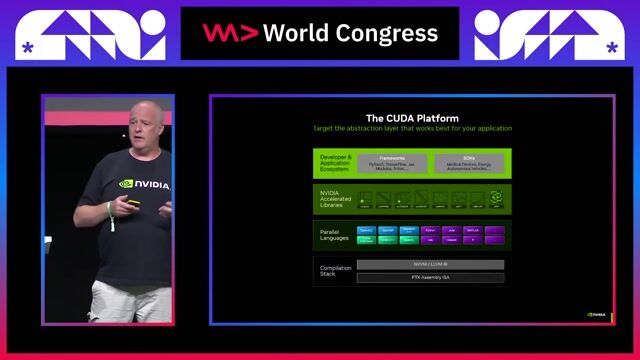
Think maximizing GPU power requires low-level CUDA syntax? Think again. Scale your Python computations using top-down frameworks, drop-in acceleration libraries, and JIT compilation for massive performance gains.
Checking access…
Playback and chapters load privately for Free videos.
4:37 min
 Paul Graham · LIVE
3:32 min
Paul Graham · World Congress 2025
1:30 min
Paul Graham · World Congress 2026 Europe
1:49 min
Paul Graham · World Congress 2026 Europe
1:37 min
 Julia Koch +1 · World Congress 2026 Europe
2:15 min
Paul Graham · World Congress 2026 Europe
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Sachin Pikle
Oracle
Product Manager

Sagar Utekar
CrowdStrike
SRE

Amith Singhee
IBM
Director, IBM Research India and AI for Z, SIL; CTO, IBM India / South Asia

Piyush Gupta
Expedia
Senior Engineering Manager

Bharat Sharma
Booking
Senior Engineering Manager
Paul Graham · NVIDIA
World Congress Europe · 2026
Stephen Jones
Coffee With Developers · Feb 2025
Ankit Patel · NVIDIA
World Congress · 2024
Jobs that call for the skills explored in this talk.