
LM
Luis Minvielle
Fast, Cheap, and Accurate: Optimizing LLM Inference with vLLM and Quantization
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
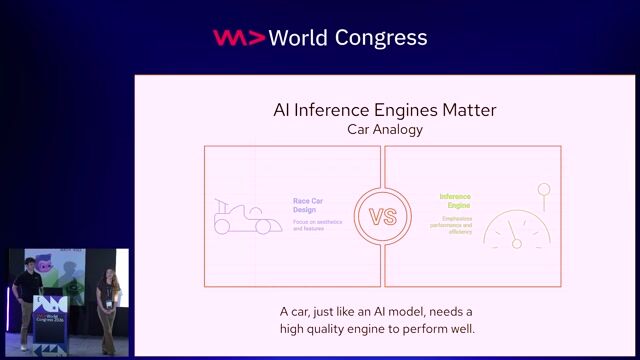
Struggling to balance cost, accuracy, and latency in your LLM deployments? Discover how vLLM and quantization can slash your VRAM needs by 50% without sacrificing performance.
Checking access…
Playback and chapters load privately for Free videos.
Matching moments
2:39 min
Open source tools for running and scaling models
 Cedric Clyburn +1 · World Congress 2025
2:44 min
Running lightweight large language models on local hardware
Ekaterina Sirazitdinova · LIVE
2:00 min
Navigating the layers of the language model inference stack
 Christin Pohl · World Congress 2026 Europe
6:15 min
Executing open weight large language models with WebLLM
 Christian Liebel · World Congress 2025
1:14 min
Evaluating AI models using an LLM as a judge
 Tomislav Tipurić +1 · World Congress 2026 North America
4:04 min
Evaluating model performance and accuracy using LLM judges
 Viktoria Semaan · World Congress 2026 North America
More from World Congress 2026 North America
Related videos
Related articles

BB
Benedikt Bischof

KD
Krissy Davis

BB
Benedikt Bischof

From learning to earning
Jobs that call for the skills explored in this talk.
about 2 months ago
•
Verified
LLM Training Engineer
Sciforium
San Francisco, United States
Expert
$155k–220k
Python
about 2 months ago
•
Verified
LLM Dataset Engineer
Sciforium
San Francisco, United States
Expert
$155k–210k
Python
about 2 months ago
•
Verified
Model Implementation Engineer
Sciforium
San Francisco, United States
Expert
$165k–220k
Python
about 2 months ago
•
Verified
Lead Software Engineer, Model Serving Platform
Sciforium
San Francisco, United States
Expert
$230k–300k
Python
about 2 months ago
•
Verified
ML Engineer
Sciforium
San Francisco, United States
Expert
$165k–210k
Python
about 1 month ago
•
Verified
ML Engineer
Docker, Inc.
Seattle, United States
Expert
Remote
Go