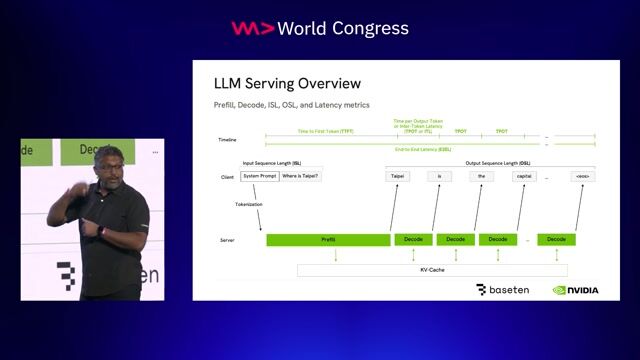






How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
Stop choosing between strict data privacy and deployment speed. Deploy optimized, GPU-accelerated LLMs securely to your infrastructure using NVIDIA NIM and LoRA adapters.
Checking access…
Playback and chapters load privately for Free videos.
2:04 min
 Ankit Patel · World Congress 2024
3:10 min
 Anshul Jindal · World Congress 2025
2:50 min
 Viktoria Semaan · World Congress 2026 Europe
5:58 min
 Hari Lingamagunta +3 · World Congress 2026 North America
2:39 min
 Cedric Clyburn +1 · World Congress 2025
1:12 min
Legare Kerrison +1 · World Congress 2026 North America
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Sagar Utekar
CrowdStrike
SRE

Aakriti Aggarwal
IBM Research
Research Engineer

Bhavishya Pandit
66degrees
Leading AI Innovation

Omkar Srivastava
ADSK
Engineering Leader

Aditya Joshi
Walmart
Senior Software Engineer

Anurag Bhandari
antelligent
CTO
Christin Pohl · Microsoft
World Congress Europe · 2026
World Congress North America · 2026
Anshul Jindal · NVIDIA
World Congress · 2025
Ankit Patel +1
World Congress North America · 2026
Dan Fu · Together AI
World Congress North America · 2026
Jobs that call for the skills explored in this talk.