












LM
Luis Minvielle
Fast, Cheap, and Accurate: Optimizing LLM Inference with vLLM and Quantization
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
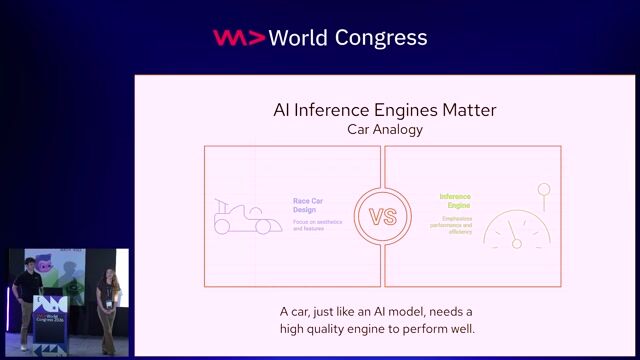
Struggling to balance cost, accuracy, and latency in your LLM deployments? Discover how vLLM and quantization can slash your VRAM needs by 50% without sacrificing performance.
Starting at 25:36 · Watch from the beginning
Checking access…
Playback and chapters load privately for Free videos.
Matching moments
2:39 min
Open source tools for running and scaling models
 Cedric Clyburn +1 · World Congress 2025
2:44 min
Running lightweight large language models on local hardware
Ekaterina Sirazitdinova · LIVE
2:00 min
Navigating the layers of the language model inference stack
 Christin Pohl · World Congress 2026 Europe
6:15 min
Executing open weight large language models with WebLLM
 Christian Liebel · World Congress 2025
1:14 min
Evaluating AI models using an LLM as a judge
 Tomislav Tipurić +1 · World Congress 2026 North America
4:04 min
Evaluating model performance and accuracy using LLM judges
 Viktoria Semaan · World Congress 2026 North America
More from World Congress 2026 North America
The Productivity Illusion: What AI Really Changed for Developers
Fatih Kadir Akın · WordPress/Automattic
Upcoming sessions on this topic
Starts in 5 days
Conference India 2026
November 25–26, 2026
Bengaluru, India
-
How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
 Purnima Kumari · DigitalOCean
Thu 26 Nov · Stage 2
-
Bypassing the GPU Tax: Smart Layer-7 Routing with Small Language Models (SLMs)
 Sagar Utekar · CrowdStrike
Thu 26 Nov · Stage 2
Related videos
Tour de Force: Open-Source LLM Inference Optimization from Simple to Sophisticated
Christin Pohl · Microsoft
World Congress Europe · 2026
Unveiling the Magic: Scaling Large Language Models to Serve Millions
Patrick Koss · STACKIT
World Congress · 2025
Cutting LLM Costs Without Cutting Quality: How to Beat Proprietary LLMs with Fine-Tuned Open Source
Viktoria Semaan · databricks
World Congress Europe · 2026
Unlocking the Power of AI: Accessible Language Model Tuning for All
World Congress · 2024
Related articles

BB
Benedikt Bischof

KD
Krissy Davis

DC
Daniel Cranney
From learning to earning
Jobs that call for the skills explored in this talk.
5 days ago
Lead Engineer, Google Cloud
PwC
Atlanta, GA, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
7 days ago
Lead Engineer, Google Cloud
PwC
Boca Raton, FL, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
7 days ago
Senior AI Scientist - Model Training & Architecture

BWI GmbH
Hamburg, Germany
Expert
€87k–113k
NoSQL
QLoRA
Docker
5 days ago
Lead Engineer, Google Cloud
PwC
Toledo, OH, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
17 days ago
Senior Engineer, Google Cloud
PwC
Richmond, VA, United States
Expert
$77k–202k
LangChain
Google Cloud
Spring Cloud
17 days ago
Senior Engineer, Google Cloud
PwC
Atlanta, GA, United States
Expert
$77k–202k
LangChain
Google Cloud
Spring Cloud