
DC
Daniel Cranney
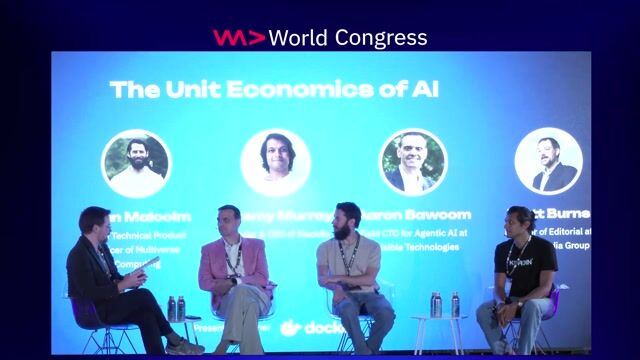
The Unit Economics of AI
Ed Huang , Jeremy Murray , John Malcolm , Aaron Bawcom , Matt Burns
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
Are skyrocketing GPU costs stalling your AI deployments? Discover how intelligent routing, agentic caching, and model compression can slash inference bills and reduce your compute footprint by 80 percent.
Checking access…
Playback and chapters load privately for Free videos.
Matching moments
5:58 min
Architecting inference layers and meta harnesses to manage token costs
 Hari Lingamagunta +3 · World Congress 2026 North America
2:26 min
Cost and latency pressures pushing AI to the edge
 Moe Sani · World Congress 2026 Europe
3:21 min
Reducing cloud dependency with on-device edge AI models
 Precious Osaro · World Congress 2026 Europe
3:07 min
Managing economic costs and intelligence scaling in AI products
Logan Kilpatrick · Coffee With Developers
1:47 min
Managing compute costs and AI model routing
 Deivids Vilkinsons +3 · World Congress 2026 Europe
5:27 min
Externalized computing costs of AI scaling
Perf + AI
More from World Congress 2026 North America
Related videos
Related articles
BB
Benedikt Bischof

LM
Luis Minvielle

ER
Erin Rifkin
CH
Chris Heilmann

From learning to earning
Jobs that call for the skills explored in this talk.
26 days ago
Principal Software Engineer, AI Inference Cloud

ARM
Seattle, WA, United States
Expert
$262k
Pytorch
TensorRT
Kubernetes
about 2 months ago
•
Verified
Lead Software Engineer, Model Serving Platform
Sciforium
San Francisco, United States
Expert
$230k–300k
Python
26 days ago
Principal Software Engineer, AI Inference Runtime
ARM
Seattle, WA, United States
Expert
$262k
Compilers
Low Latency
Concurrency
about 2 months ago
•
Verified
Senior AI Serving Engineer, Backend
Sciforium
San Francisco, United States
Expert
$190k–250k
Rust
Python
26 days ago
Principal Software Engineer, AI Compute Infrastructure
ARM
Seattle, WA, United States
Expert
$262k
Linux
Grafana
Pytorch
about 2 months ago
•
Verified
GPU Cluster Engineer, Systems & Platform
Sciforium
San Francisco, United States
Expert
$150k–220k
Kubernetes