













DC
Daniel Cranney
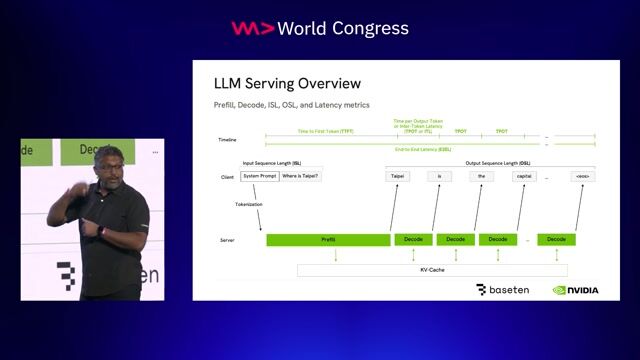
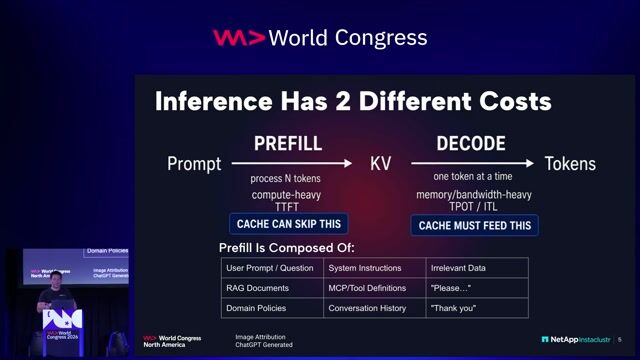
Anatomy of an AI Request: Where Latency and Cost Are Really Born
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
Running pre-fill and decode on the same GPU severely bottlenecks your AI throughput. Discover how cache-aware disaggregation and speculative decoding can drastically reduce latency and infrastructure costs.
Checking access…
Playback and chapters load privately for Free videos.
Matching moments
5:58 min
Architecting inference layers and meta harnesses to manage token costs
 Hari Lingamagunta +3 · World Congress 2026 North America
1:47 min
Managing compute costs and AI model routing
 Deivids Vilkinsons +3 · World Congress 2026 Europe
3:20 min
Optimizing AI infrastructure from applications to GPU kernels
 Erran Berger +1 · World Congress 2026 North America
1:52 min
Prioritizing developer user experience over raw model parameters
 Neel Sundaresan +1 · World Congress 2026 Europe
2:37 min
Understanding core parameters and mechanics of large language models
 Julián Duque · World Congress 2025
1:47 min
Balancing scale and architecture in artificial intelligence development
 Yuval Dvir · World Congress 2026 North America
More from World Congress 2026 North America
The Productivity Illusion: What AI Really Changed for Developers
Fatih Kadir Akın · WordPress/Automattic
Upcoming sessions on this topic
Starts in 5 days
Conference India 2026
November 25–26, 2026
Bengaluru, India
-
How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
 Purnima Kumari · DigitalOCean
Thu 26 Nov · Stage 2
-
Bypassing the GPU Tax: Smart Layer-7 Routing with Small Language Models (SLMs)
 Sagar Utekar · CrowdStrike
Thu 26 Nov · Stage 2
Related videos
Compute for your AI model: GPUs, LPUs, TPUs and beyond..
Kushaagra Goyal · Rubrik
World Congress North America · 2026
A Hands-On Developer Guide to Inference Engineering
Ankit Patel +1
World Congress North America · 2026
Tour de Force: Open-Source LLM Inference Optimization from Simple to Sophisticated
Christin Pohl · Microsoft
World Congress Europe · 2026
KV Cache Is Not About Speed: It's About Surviving Inference Costs
David vonThenen · NetApp
World Congress North America · 2026
Related articles
BB
Benedikt Bischof

BB
Benedikt Bischof

DC
Daniel Cranney
From learning to earning
Jobs that call for the skills explored in this talk.
5 days ago
Lead Engineer, Google Cloud
PwC
Atlanta, GA, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
7 days ago
Senior AI Scientist - Model Training & Architecture

BWI GmbH
Hamburg, Germany
Expert
€87k–113k
NoSQL
QLoRA
Docker
9 days ago
AI Scientist - Model Training & Architecture
BWI GmbH
Bamberg, Germany
Expert
€87k–113k
NoSQL
QLoRA
Docker
7 days ago
Lead Engineer, Google Cloud
PwC
Boca Raton, FL, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
5 days ago
Lead Engineer, Google Cloud
PwC
Toledo, OH, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
about 2 months ago
•
AI Software Engineer (Germany)
Sunhat
Berlin, Germany
Expert
€70k–100k
Remote
REST
TypeScript
AI Frameworks