
DC
Daniel Cranney
Compute for your AI model: GPUs, LPUs, TPUs and beyond..
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
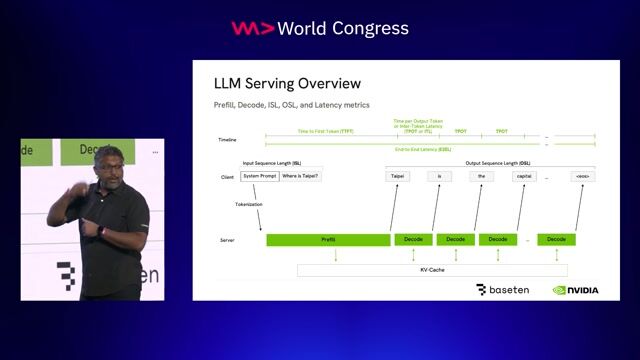
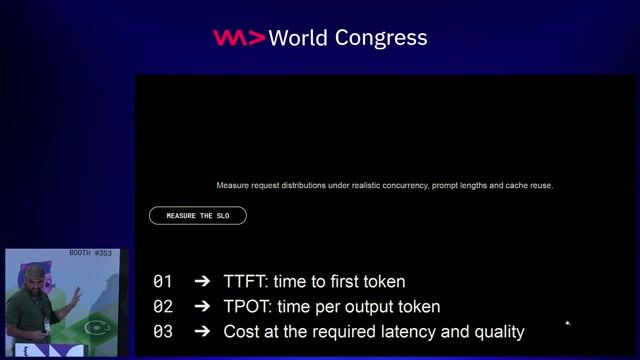
Is your shared hardware starving your AI model's decode phase? Learn to slash inference latency using disaggregated serving across specialized GPUs, TPUs, and SRAM-dense LPUs.
Checking access…
Playback and chapters load privately for Free videos.
Matching moments
1:47 min
Balancing scale and architecture in artificial intelligence development
 Yuval Dvir · World Congress 2026 North America
3:18 min
Hardware architectures tailored for specific artificial intelligence computations
 Stephan Gillich · World Congress 2024
1:32 min
Escalating compute demands for production generative AI inference
 Thomas Schmidt · World Congress 2024
2:07 min
Lowering inference costs through specialized hardware architectures
 Ed Huang +4 · World Congress 2026 North America
2:00 min
Selecting purpose-built hardware for model training and inference
Sohan Maheshwar · LIVE
1:47 min
Managing compute costs and AI model routing
 Deivids Vilkinsons +3 · World Congress 2026 Europe
More from World Congress 2026 North America
Related videos
Related articles
BB
Benedikt Bischof

LM
Luis Minvielle

MH
Michael Hunger
N
Neo4j
From learning to earning
Jobs that call for the skills explored in this talk.
25 days ago
Principal Software Engineer, AI Inference Runtime

ARM
Seattle, WA, United States
Expert
$262k
Compilers
Low Latency
Concurrency
about 2 months ago
•
Verified
LLM Training Engineer
Sciforium
San Francisco, United States
Expert
$155k–220k
Python
25 days ago
Principal Software Engineer, AI Inference Cloud
ARM
Seattle, WA, United States
Expert
$262k
Pytorch
TensorRT
Kubernetes
25 days ago
Staff Software Engineer, AI Inference Runtime
ARM
Seattle, WA, United States
Expert
$209k–282k
Compilers
Low Latency
Concurrency
about 2 months ago
•
Verified
Distributed Training and Inference Engineer
Sciforium
San Francisco, United States
Expert
$190k–250k
Linux kernel
about 2 months ago
•
Verified
GPU Kernel Engineer
Sciforium
San Francisco, United States
Expert
$190k–250k
PyTorch