
DA
Dr. Andy R. Terrel - NVIDIA
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
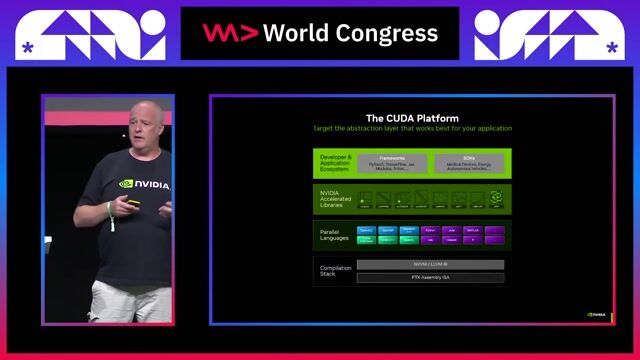
Astrophysicists boosted data processing speeds 39x without writing any low-level C++. Discover how the CUDA Python ecosystem accelerates your workloads using simple library drop-ins.
Matching moments
4:37 min
Simplifying parallel programming with the CUDA ecosystem
 Paul Graham · LIVE
2:15 min
Introduction to CUDA and general-purpose GPU computing
Paul Graham · World Congress 2026 Europe
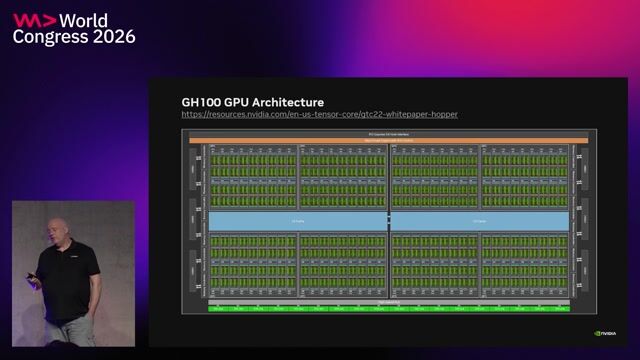
1:30 min
Exploring the Python-enabled GPU programming software stack
Paul Graham · World Congress 2026 Europe
1:49 min
Accelerating script execution with CuPy and Numba kernels
Paul Graham · World Congress 2026 Europe
1:37 min
Accelerating compute with focused developer tools
 Julia Koch +1 · World Congress 2026 Europe
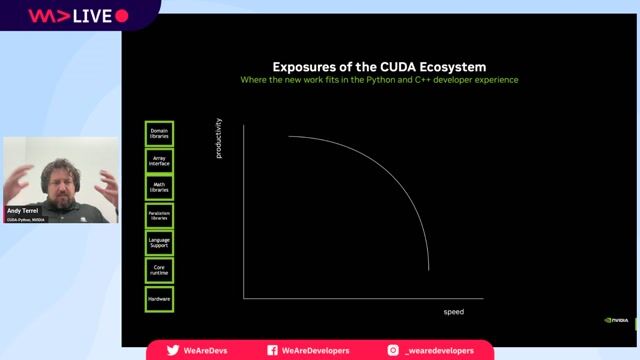
1:11 min
The expanded CUDA ecosystem and native Python support
Paul Graham · World Congress 2026 Europe
More from World Congress 2025
Related videos
Related articles

DC
Daniel Cranney

BB
Benedikt Bischof

DC
Daniel Cranney

From learning to earning
Jobs that call for the skills explored in this talk.
about 1 month ago
•
Verified
GPU Cluster Engineer, Systems & Platform
Sciforium
San Francisco, United States
Expert
$150k–220k
Kubernetes
about 1 month ago
•
Verified
GPU Kernel Engineer
Sciforium
San Francisco, United States
Expert
$190k–250k
PyTorch
21 days ago
Principal Software Engineer, AI Compute Infrastructure

ARM
Seattle, WA, United States
Expert
$262k
Linux
Grafana
Pytorch
about 1 month ago
•
Verified
Lead Software Engineer, Model Serving Platform
Sciforium
San Francisco, United States
Expert
$230k–300k
Python
about 1 month ago
•
Verified
Distributed Training and Inference Engineer
Sciforium
San Francisco, United States
Expert
$190k–250k
Linux kernel
about 1 month ago
•
Verified
GPU Cluster Engineer, Hardware Operations
Sciforium
San Francisco, United States
Expert
$150k–180k
Network Infrastructure