









BB
Benedikt Bischof
WeAreDevelopers LIVE
•
May 26, 2021
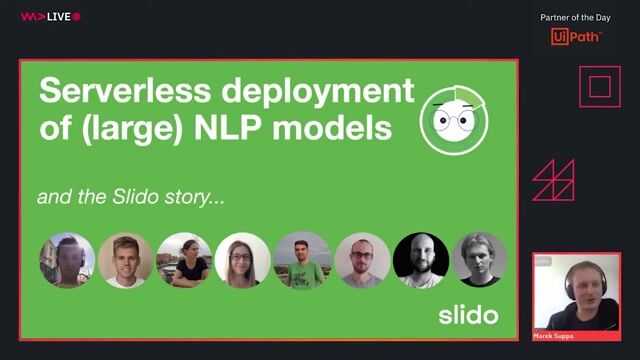
Serverless deployment of (large) NLP models
Marek Suppa
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
Can you run massive NLP models within AWS Lambda's strict 250MB limit? Discover how Slido used knowledge distillation and ONNX to achieve sub-100ms serverless inference.
Starting at 8:53 · Watch from the beginning
Checking access…
Playback and chapters load privately for Free videos.
Matching moments
1:33 min
Scaling model inference leveraging serverless edge functions
 Jeremy Murray · World Congress 2026 Europe
1:20 min
Reducing infrastructure capacity requirements by deploying small language models
 Alexander Wallner +3 · World Congress 2024
2:50 min
Executing LoRA fine-tuning using serverless Databricks AI runtimes
 Viktoria Semaan · World Congress 2026 Europe
1:45 min
Introduction to serving large language models locally
 Patrick Koss · World Congress 2025
2:44 min
Running lightweight large language models on local hardware
Ekaterina Sirazitdinova · LIVE
5:05 min
Exploring hybrid models, monoliths, and serverless computing
Michael Eisenbart · LIVE
More from WeAreDevelopers LIVE
Upcoming sessions on this topic
Starts in 5 days
Conference India 2026
November 25–26, 2026
Bengaluru, India
-
Bypassing the GPU Tax: Smart Layer-7 Routing with Small Language Models (SLMs)
 Sagar Utekar · CrowdStrike
Thu 26 Nov · Stage 2
Related videos
Unveiling the Magic: Scaling Large Language Models to Serve Millions
Patrick Koss · STACKIT
World Congress · 2025
Leverage Cloud Computing Benefits with Serverless Multi-Cloud ML
Linda Mohamed
LIVE · Nov 2020
Fast, Cheap, and Accurate: Optimizing LLM Inference with vLLM and Quantization
World Congress North America · 2026
Tour de Force: Open-Source LLM Inference Optimization from Simple to Sophisticated
Christin Pohl · Microsoft
World Congress Europe · 2026
DevOps for AI: running LLMs in production with Kubernetes and KubeFlow
Aarno Aukia
LIVE · Oct 2024
Related articles

BB
Benedikt Bischof

LM
Luis Minvielle

BB
Benedikt Bischof

From learning to earning
Jobs that call for the skills explored in this talk.
6 days ago
Senior AI Scientist - Model Training & Architecture

BWI GmbH
Hamburg, Germany
Expert
€87k–113k
NoSQL
QLoRA
Docker
20 days ago
Machine Learning Engineer 2

Twilio
San Francisco, CA, United States
$128k–160k
Remote
Twilio
Backend
Raw Data
about 2 months ago
•
AI Software Engineer (Germany)
Sunhat
Berlin, Germany
Expert
€70k–100k
Remote
REST
TypeScript
AI Frameworks
8 days ago
AI Scientist - Model Training & Architecture
BWI GmbH
Bamberg, Germany
Expert
€87k–113k
NoSQL
QLoRA
Docker
16 days ago
•
Senior Data & AI Architect
reeeliance IM GmbH
Berlin, Germany
Expert
Hybrid · 3 days on-site · Remote
Python
Microsoft SQL Server
Cloud (AWS/Google/Azure)
4 days ago
Lead Engineer, Google Cloud
PwC
Atlanta, GA, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI