WeAreDevelopers LIVE • Feb 23, 2024

Accelerating Python on GPUs

Paul Graham

Paul Graham proves you can unlock massive GPU compute power in Python without touching C++. Discover the multi-tiered path from zero-code pandas acceleration to custom PyCUDA integrations.

Pause
Mute Enter Fullscreen
#1 about 3 min

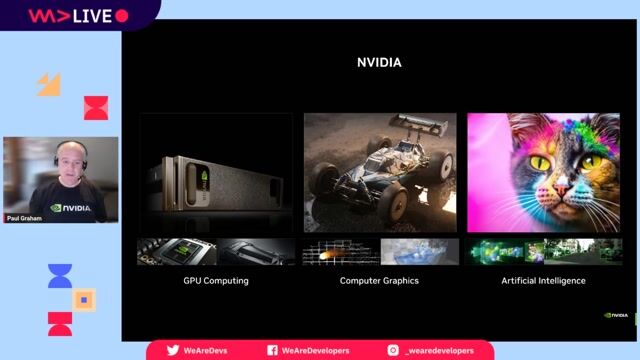
History and scale of NVIDIA GPU computing

The transition of GPUs from graphics rendering engines to general-purpose computing processors and deep learning accelerators.

#2 about 4 min

Comparing single-threaded CPU performance and parallel GPU architectures

How physical limitations in single-core CPU scaling drove the adoption of parallel GPU processing architectures.

#3 about 2 min

Offloading computational bottlenecks from CPUs to GPUs

The fundamental workflow of delegating time-consuming parallel loops to the GPU while the CPU handles sequential logic.

#4 about 6 min

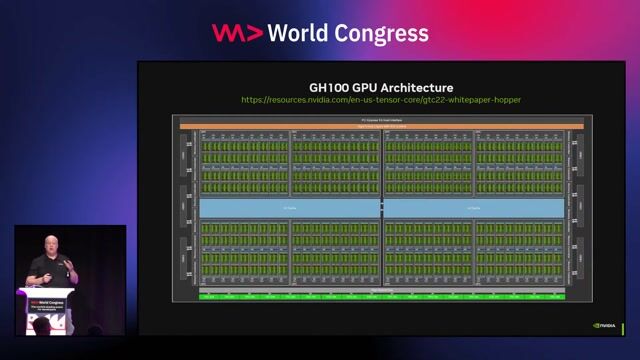
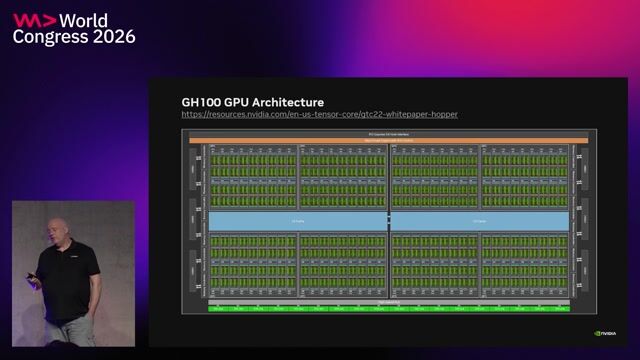
Analyzing hardware components inside a modern GPU architecture

How streaming multiprocessors and specialized cores use high-thread-count execution to hide latency dynamically.

#5 about 2 min

Scaling applications across multi-node GPU clusters and architectures

How data movement considerations and hardware technologies shape multi-gpu communication and system scale-out operations.

#6 about 5 min

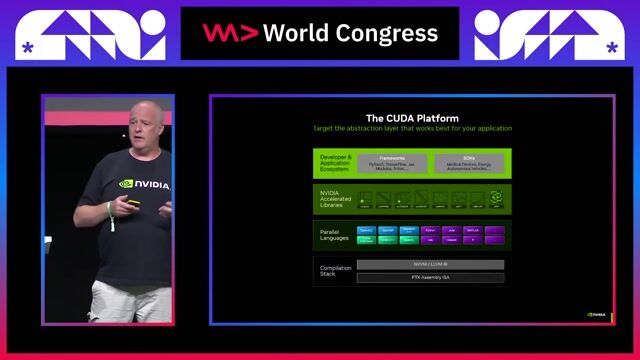
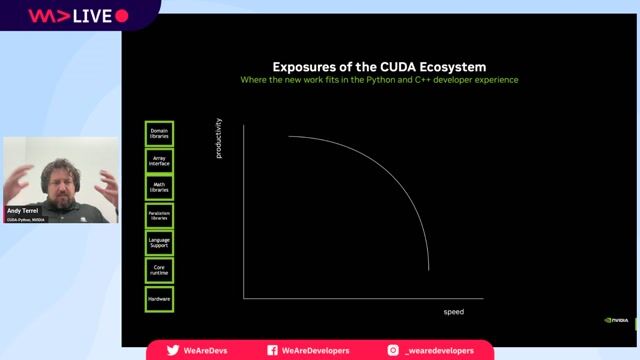
Simplifying parallel programming with the CUDA ecosystem

The evolution of abstraction layers and compilers that allow developers to execute C++ and Python code on GPUs without graphics APIs.

#7 about 4 min

Leveraging tensor cores for deep neural network execution

Exploiting specialized matrix multiply-accumulate hardware through automated mixed-precision libraries and lower-level developer interfaces.

#8 about 3 min

Exploring high-level Python frameworks for accelerated enterprise artificial intelligence

A review of application-specific libraries for routing, speech recognition, large language models, and physics-informed neural networks.

#9 about 4 min

Refactoring data science workflows using Rapids QDF and Pandas

Achieving extreme performance scaling in data preparation pipelines by swapping standard libraries for GPU-optimized equivalents.

#10 about 4 min

Transitioning into custom parallel computing implementations using Python

A stepwise approach to optimizing unique workloads by introducing specific computational libraries and incremental compilation directives.

#11 about 2 min

Extending distributed parallel processing capabilities using QNumeric arrays

Distributing implicit matrix parallelization techniques across thousands of nodes transparently through a drop-in NumPy replacement.

#12 about 4 min

Applying targeted just-in-time compilation rules with Python Numba

Controlling low-level memory allocation and individual thread execution paths using typed decorators within analytical Python logic.

#13 about 2 min

Implementing specialized device kernels using CuPy and PyCUDA

Writing pure C or C++ kernel structures to exact maximal control and performance within Python scripting environments.

#14 about 3 min

Analyzing logic and performance metrics via developer profiling tools

Isolating execution bottlenecks, race conditions, and out-of-bounds memory leaks using correctness checkers and roofline analysis utilities.

#15 about 5 min

Accessing preconfigured environments via the NGC software repository

Obtaining pre-trained state-of-the-art models and monthly optimized containers from a centralized machine learning distribution registry.

#16 about 4 min

Deploying inference architectures on mobile edge computing endpoints

Adapting data center memory boundaries and network architectures to function securely alongside strict low-power specifications.

#17 about 2 min

Navigating emerging hardware standardization in vendor programming ecosystems

The migration from proprietary optimization languages toward universal backend compilers that support distinct hardware architectures.

#18 about 2 min

Evaluating absolute performance thresholds between Python and procedural syntaxes

Understanding when high-level scripting wrappers produce overhead compared to native implementation code during aggressive optimization cycles.

#19 about 3 min

Shaping future physical logic gates with deep learning requirements

How algorithmic phenomena like transformer models directly inspire novel transistor arrangements and mixed-precision capabilities.

#20 about 3 min

Evaluating remote hardware allocations for localized infrastructure constraints

Using local subsystems or cloud-hosted instances to experiment with GPU-accelerated code when strict budget boundaries exist.

#21 about 2 min

Forecasting compiler intelligence and declarative syntactic features in computing

Anticipating runtime automation protocols that abstract complex data pipeline topologies from standard algorithmic structures.

#22 about 2 min

Container orchestration and scalability dynamics affecting cloud infrastructure performance

Developing enclosed analytical experiments via localized instances before deploying complex training epochs across large remote computational clusters.

Matching moments

3:32 min

Evolution of general purpose GPU computing and Python

Paul Graham Paul Graham · World Congress 2025

1:30 min

Exploring the Python-enabled GPU programming software stack

Paul Graham Paul Graham · World Congress 2026 Europe

2:15 min

Introduction to CUDA and general-purpose GPU computing

Paul Graham Paul Graham · World Congress 2026 Europe

1:49 min

Accelerating script execution with CuPy and Numba kernels

Paul Graham Paul Graham · World Congress 2026 Europe

1:37 min

Accelerating compute with focused developer tools

Julia Koch Julia Koch +1 · World Congress 2026 Europe

2:27 min

Exploring the CUDA ecosystem and levels of abstraction

Paul Graham Paul Graham · World Congress 2025

