


DC
Daniel Cranney
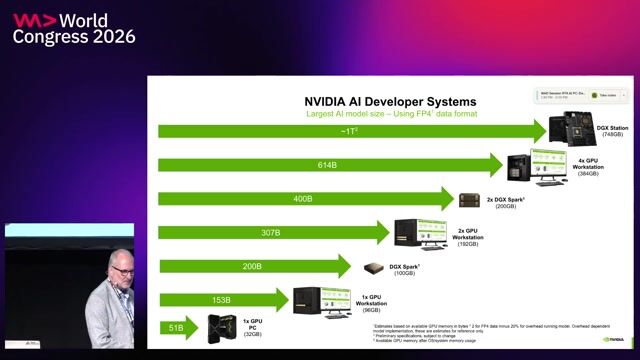
RTX AI PC: Developing local and edge AI applications
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
For under a dollar, you can now fine-tune personalized AI models locally. Discover how RTX hardware eliminates cloud dependencies to power frictionless, zero-latency edge applications.
Matching moments
54 sec
Running generative AI models in local environments
 Cedric Clyburn · World Congress 2024
2:26 min
Cost and latency pressures pushing AI to the edge
 Moe Sani · World Congress 2026 Europe
3:21 min
Reducing cloud dependency with on-device edge AI models
 Precious Osaro · World Congress 2026 Europe
2:12 min
Distilling cloud AI capabilities into local device models
2:54 min
Leveraging Chrome AI and nano models for web applications
Raymond Camden · Perf + AI
3:19 min
Technological shifts enabling practical edge AI deployment
 Sasha Denisov · World Congress 2026 Europe
More from World Congress 2026 Europe
Related videos
Related articles

BB
Benedikt Bischof

MH
Michael Hunger
N
Neo4j

BB
Benedikt Bischof
From learning to earning
Jobs that call for the skills explored in this talk.
16 days ago
Principal Software Engineer, AI Compute Infrastructure

ARM
Seattle, WA, United States
Expert
$262k
Linux
Grafana
Pytorch
16 days ago
Principal Software Engineer, AI Inference Cloud
ARM
Seattle, WA, United States
Expert
$262k
Pytorch
TensorRT
Kubernetes
16 days ago
Principal Software Engineer, AI Inference Runtime
ARM
Seattle, WA, United States
Expert
$262k
Compilers
Low Latency
Concurrency
about 1 month ago
•
Verified
LLM Training Engineer

Sciforium
San Francisco, United States
Expert
$155k–220k
Python
1 day ago
•
Verified
AI Software Engineer (Germany)
Sunhat
Berlin, Germany
Expert
€70k–100k
Remote
REST
TypeScript
AI Frameworks
about 1 month ago
•
Verified
GPU Cluster Engineer, Systems & Platform
Sciforium
San Francisco, United States
Expert
$150k–220k
Kubernetes