





Did the Model Improve, or Just the Score? A Developer’s Guide to LLM Evaluation
-

Jack Fitzsimons
Blatent
CTO and Co-Founder
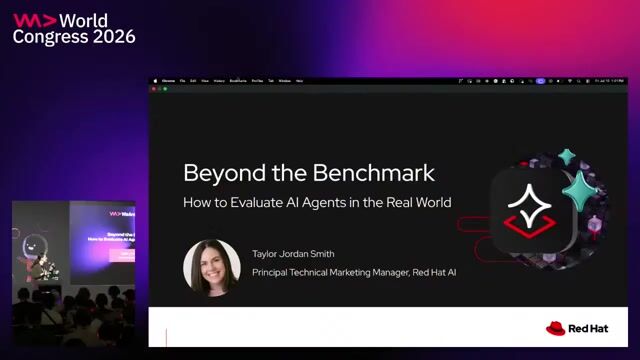
Tyler Smith reveals that high benchmark scores mask fundamental AI execution failures. Ditch the happy-path demo and evaluate production agents using full-stack observability and continuous telemetry.
Checking access…
Playback and chapters load privately for Free videos.
2:28 min
 Max Tkacz · World Congress 2025
1:56 min
 Sofia Rest · World Congress 2026 North America
2:34 min
Sofia Rest · World Congress 2026 North America
2:40 min
 Ingo Eichhorst · World Congress 2026 Europe
2:43 min
 Marcel Scherenberg · World Congress 2025
1:00 min
 Manuel Weichselbaum · World Congress 2026 Europe
Christian Heilmann · WeAreDevelopers
David vonThenen · NetApp
Irina Branovic · adjoe
Jack Fitzsimons
Blatent
CTO and Co-Founder

Sajeetharan Sinnathurai
Microsoft
Principal Product Manager

Haimantika Mitra
Entire
Senior Developer Advocate

Anthony Nguyen
LaunchDarkly
Senior Solutions Engineer

Navin Pai
StackGen
Director of Engineering

Nagendra Bangalore
IBM
Director of Engineering
Liran Hason · Coralogix
World Congress Europe · 2026
Chris Waterson · Guild.ai
World Congress North America · 2026
World Congress North America · 2026
Julia Furst Morgado · Dash0
World Congress North America · 2026
Mitesh Patel +3
World Congress North America · 2026
Jobs that call for the skills explored in this talk.