












LM
Luis Minvielle
The New Bottleneck in Software Development
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
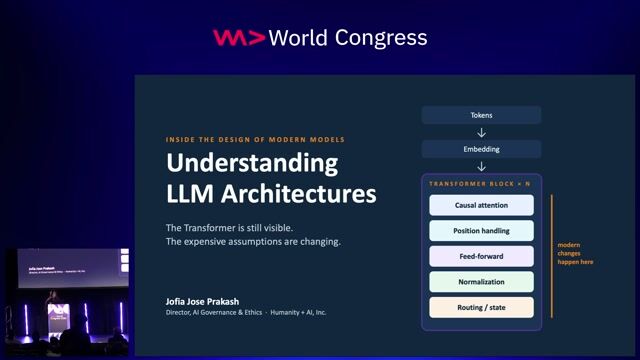
The KV cache is the new memory bottleneck crippling generative AI applications. Learn how modern architectures like Grouped-Query Attention overcome this limit to optimize your production workloads.
Checking access…
Playback and chapters load privately for Free videos.
Matching moments
1:05 min
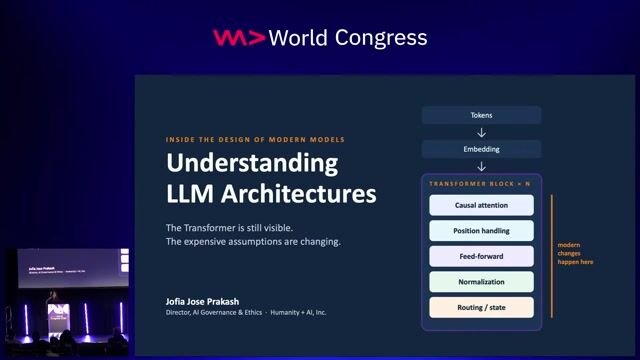
Evaluating language models by understanding underlying architectural changes
 Jofia Jose Prakash · World Congress 2026 North America
1:17 min
Understanding the unique architecture of LLM applications
 Saloni Garg · World Congress 2026 North America
2:37 min
Understanding core parameters and mechanics of large language models
 Julián Duque · World Congress 2025
7:28 min
Accelerating product features using generative large language models
David Singleton +1 · Coffee With Developers
5:01 min
Leveraging large language models for code optimization and development
 Stephan Gillich +3 · World Congress 2024
2:26 min
Capabilities and applications of large language models
Aditi Godbole · LIVE
More from World Congress 2026 North America
The Productivity Illusion: What AI Really Changed for Developers
Fatih Kadir Akın · WordPress/Automattic
Upcoming sessions on this topic
Starts in 5 days
Conference India 2026
November 25–26, 2026
Bengaluru, India
-
Bypassing the GPU Tax: Smart Layer-7 Routing with Small Language Models (SLMs)
 Sagar Utekar · CrowdStrike
Thu 26 Nov · Stage 2
-
Recursive Language Models: Scaling infinitely beyond the Context Window
 Jayita Bhattacharyya · Domyn
Thu 26 Nov · Stage 3 - powered by GitHub
-
How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
 Purnima Kumari · DigitalOCean
Thu 26 Nov · Stage 2
Related videos
Understanding LLM Architectures: Inside the Design of Modern Models
Jofia Jose Prakash · Humanity + AI, Inc
World Congress North America · 2026
Unveiling the Magic: Scaling Large Language Models to Serve Millions
Patrick Koss · STACKIT
World Congress · 2025
Tour de Force: Open-Source LLM Inference Optimization from Simple to Sophisticated
Christin Pohl · Microsoft
World Congress Europe · 2026
The LLM Evolution: From Sequence Imitation to Verifiable Reasoning
Kamen Petroff · ATOS
World Congress Europe · 2026
Related articles

MH
Michael Hunger
N
Neo4j
BB
Benedikt Bischof

BB
Benedikt Bischof

From learning to earning
Jobs that call for the skills explored in this talk.
5 days ago
Lead Engineer, Google Cloud
PwC
Atlanta, GA, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
7 days ago
Lead Engineer, Google Cloud
PwC
Boca Raton, FL, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
5 days ago
Lead Engineer, Google Cloud
PwC
Toledo, OH, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
17 days ago
Senior Engineer, Google Cloud
PwC
Richmond, VA, United States
Expert
$77k–202k
LangChain
Google Cloud
Spring Cloud
17 days ago
Senior Engineer, Google Cloud
PwC
Las Vegas, NV, United States
Expert
$77k–202k
LangChain
Google Cloud
Spring Cloud
17 days ago
Senior Engineer, Google Cloud
PwC
Detroit, MI, United States
Expert
$77k–202k
LangChain
Google Cloud
Spring Cloud