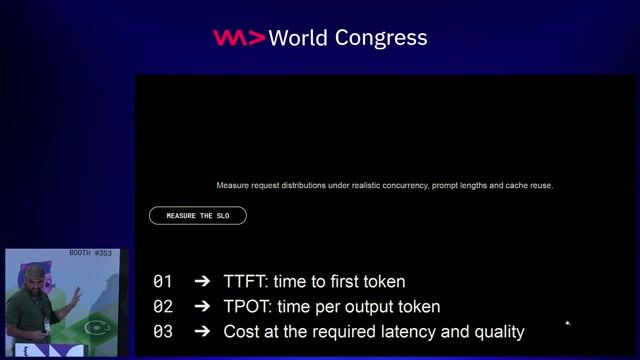
How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
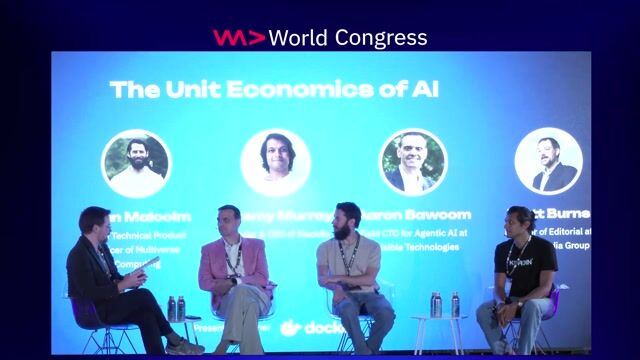
Ed Huang , Jeremy Murray , John Malcolm , Aaron Bawcom , Matt Burns
Are skyrocketing GPU costs stalling your AI deployments? Discover how intelligent routing, agentic caching, and model compression can slash inference bills and reduce your compute footprint by 80 percent.
Checking access…
Playback and chapters load privately for Free videos.
5:58 min
 Hari Lingamagunta +3 · World Congress 2026 North America
2:26 min
 Moe Sani · World Congress 2026 Europe
3:21 min
 Precious Osaro · World Congress 2026 Europe
3:07 min
1:47 min
 Deivids Vilkinsons +3 · World Congress 2026 Europe
5:27 min
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Bharat Sharma
Booking
Senior Engineering Manager

Aishwarya Mathuria
Adobe
Computer Scientist

Nishant Thakur
Adobe
Senior Computer Scientist

Suriya Prakash B
Red Hat
Principal Software Engineer

Amol Sharma
Stripe
Engineering Manager

Pushkar Mishra
J.P. Morgan
Senior Vice President
Jobs that call for the skills explored in this talk.