



How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
Andy Terrel
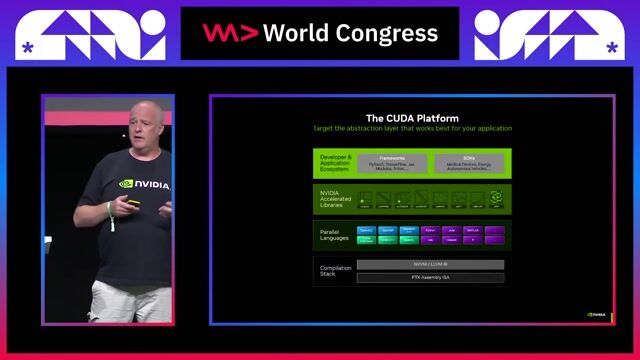
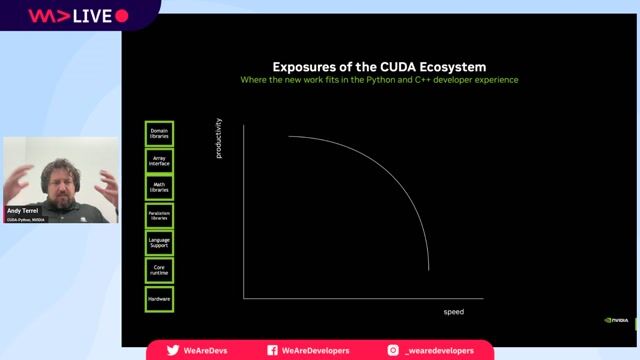
Tired of choosing between Python productivity and C++ hardware speed? Discover how new CUDA tools finally give developers low-level GPU control for maximum performance directly in Python.
Checking access…
Playback and chapters load privately for Free videos.
1:11 min
 Paul Graham · World Congress 2026 Europe
4:37 min
Paul Graham · LIVE
1:51 min
Paul Graham · World Congress 2025
2:27 min
Paul Graham · World Congress 2025
1:49 min
Paul Graham · World Congress 2026 Europe
1:37 min
 Julia Koch +1 · World Congress 2026 Europe
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Sachin Pikle
Oracle
Product Manager

Frederik Pietzko
Jetbrains
Developer Advocate

Piyush Gupta
Expedia
Senior Engineering Manager

Amith Singhee
IBM
Director, IBM Research India and AI for Z, SIL; CTO, IBM India / South Asia

Aryan Saini
sktime
AI engineer

Franz Kiraly
sktime
Director

Jigyasu ㅤ
sktime
Core developer

Shashank Shekhar Singh
Sktime
Open Source Developer
Paul Graham · NVIDIA
World Congress Europe · 2026
Stephen Jones
Coffee With Developers · Feb 2025
Ankit Patel · NVIDIA
World Congress · 2024
Jobs that call for the skills explored in this talk.