



How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
Fabian Schindler
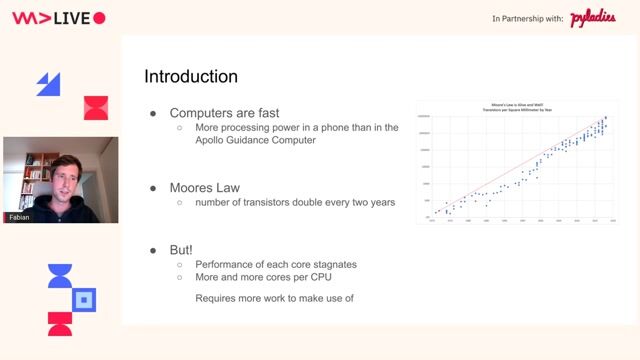
Is your Python app struggling to scale? Master asyncio to bypass the Global Interpreter Lock and build high-performance services that handle thousands of concurrent clients.
Starting at 24:24 · Watch from the beginning
Checking access…
Playback and chapters load privately for Free videos.
2:59 min
2:10 min
2:34 min
9:07 min
2:31 min
 Rick Rackow · World Congress 2026 Europe
1:34 min
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Sachin Pikle
Oracle
Product Manager

Shuchita Prasad
JPMorgan
Senior Lead Engineer

Deepak Agrawal
Atlassian
Principal Software Engineer

Prakhar Goel
Adalat AI
Platform Enginner

Ajeet Raina
Docker
Developer Advocate
Rick Rackow · Schwarz Digits
World Congress Europe · 2026
Jobs that call for the skills explored in this talk.