World Congress 2024 • Aug 20, 2024 • Session details

Efficient deployment and inference of GPU-accelerated LLMs​

Adolf Hohl

Stop choosing between strict data privacy and deployment speed. Deploy optimized, GPU-accelerated LLMs securely to your infrastructure using NVIDIA NIM and LoRA adapters.

Pause
Mute Enter Fullscreen
#1 about 3 min

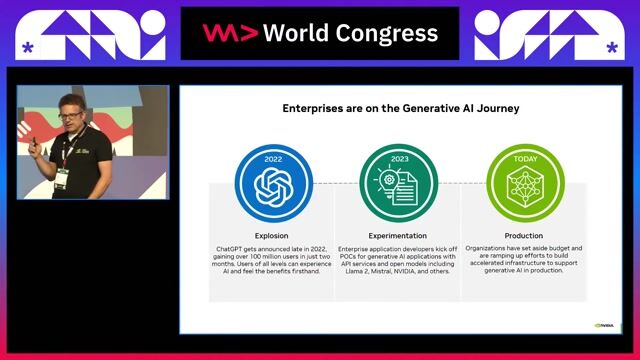
Transitioning generative AI from experimentation to production

The evolution of AI models from early breakthroughs to widespread production deployment stages.

#2 about 3 min

Evaluating managed AI services versus self-hosted infrastructure

Trade-offs between fully managed endpoints and building custom deployment infrastructure for complete environmental control.

#3 about 3 min

Streamlining model deployment with containerized microservice architectures

Utilizing containerized microservices as an immediate plug-and-play replacement for standardized application programming interfaces.

#4 about 2 min

Comparing pre-packaged microservices against manual model deployments

How pre-packaged solutions reduce deployment time from weeks to minutes while enforcing reliable interfaces.

#5 about 2 min

Maximizing hardware throughput via reduced model precision

Applying variable precision formats to substantially extract higher inference throughput and better economic sustainability.

#6 about 2 min

Abstracting low-level infrastructure with end-to-end software platforms

Obscuring complex accelerator communications to easily maintain reliable and scalable generative cloud pipelines.

#7 about 3 min

Core libraries driving inference engines and multi-GPU networking

How specialized runtime components manage hardware heuristics and parameter distribution across multiple distributed accelerators.

#8 about 3 min

Analyzing container hardware discovery and request batching workflows

The automated boot process where containers detect device topology before directing requests through specialized execution logic.

#9 about 3 min

Minimizing memory footprint using simultaneous adapter representation layers

Mounting multiple lightweight parameter adapters atop a base network to execute distinct application tasks concurrently.

#10 about 3 min

Handling optimal pre-built model configurations in isolated networks

The automated decision tree for selecting robust engine configurations across disconnected or distinct physical architectures.

Matching moments

2:04 min

Optimizing and deploying containerized AI inference workloads

Ankit Patel Ankit Patel · World Congress 2024

3:10 min

Scaling customized inference models with NVIDIA NIM

Anshul Jindal Anshul Jindal · World Congress 2025

2:50 min

Executing LoRA fine-tuning using serverless Databricks AI runtimes

Viktoria Semaan Viktoria Semaan · World Congress 2026 Europe

5:58 min

Architecting inference layers and meta harnesses to manage token costs

Hari Lingamagunta Hari Lingamagunta +3 · World Congress 2026 North America

2:39 min

Open source tools for running and scaling models

Cedric Clyburn Cedric Clyburn +1 · World Congress 2025

1:12 min

Using vLLM recipes for optimal local hardware configuration

Legare Kerrison Legare Kerrison +1 · World Congress 2026 North America

Upcoming sessions on this topic

Open session

How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design

  • Purnima Kumari

    DigitalOCean

    Sr. Solutions Architect II

Open session

Build a Zero-Cost AI Agent in Your Browser

  • Aishwarya Mathuria

    Adobe

    Computer Scientist

  • Nishant Thakur

    Adobe

    Senior Computer Scientist

Open session

Architecting Trusted AI: Coupling Multi-Agent Systems with dbt Semantic Store for Zero-Hallucination

  • Pushkar Mishra

    J.P. Morgan

    Senior Vice President

Open session

From Prompt Engineering to Harness Engineering: Building Observable and Governed GenAI Systems

  • Lakshmi Devi Prakash

    JPMorgan Chase

    VP, Applied AI/ML Lead

Open session

React Under Fire: Rendering Performance for Streaming Agent UIs

  • Abhirupa Mitra

    Slack

    Senior Member of Technical Staff

Open session

Agentic Forecasting with sktime: Towards Autonomous Time Series Analysis

  • Franz Kiraly

    sktime

    Director