AH
Aishi Huang
CH
Chris Heilmann
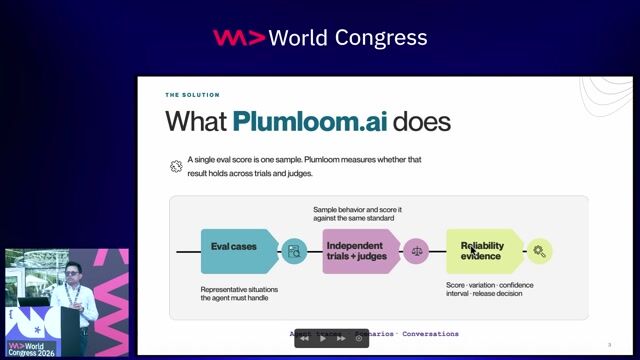
Stop relying on flaky LLM evaluations for deployment decisions. Plumloom uses independent judges and statistical confidence intervals to automatically block bad AI releases in your pipeline.
Checking access…
Playback and chapters load privately for Free videos.
2:36 min
 Saloni Garg · World Congress 2026 North America
1:56 min
 Sofia Rest · World Congress 2026 North America
1:31 min
 Anita Ganti · World Congress 2026 North America
4:42 min
 Viktoria Semaan · World Congress 2026 Europe
2:49 min
 Csenge Szabo · Europe 2026 Virtual
4:04 min
Viktoria Semaan · World Congress 2026 North America
Jobs that call for the skills explored in this talk.