



How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
Anirudh Koul
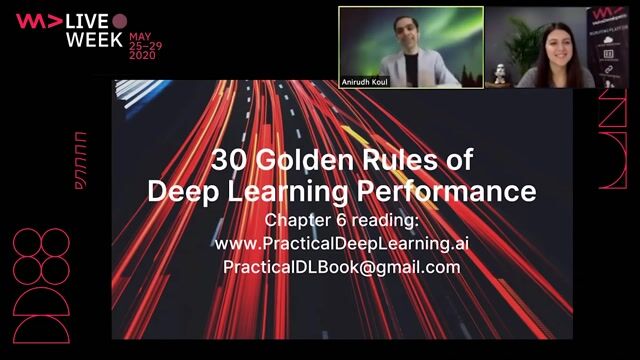
Stop buying more compute power to fix GPU starvation. Discover how serializing datasets, shifting augmentation, and using mixed precision can exponentially accelerate your deep learning pipelines.
Checking access…
Playback and chapters load privately for Free videos.
4:15 min
 Dan Fu · World Congress 2026 North America
1:20 min
 Wayne Liu · World Congress 2026 North America
46 sec
 Magne Johansen · Europe 2026 Virtual
1:44 min
 Lerna Ekmekcioglu · Europe 2026 Virtual
4:58 min
2:00 min
 Ankit Patel · World Congress 2024
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Sagar Utekar
CrowdStrike
SRE

Aditya Dua
GitHub
Senior Manager, Field Services, SAARC

Omkar Srivastava
ADSK
Engineering Leader

Bharat Sharma
Booking
Senior Engineering Manager

Sandeep S. Nair
Microsoft
Principal Program Manager
Kushaagra Goyal · Rubrik
World Congress North America · 2026
Dan Fu · Together AI
World Congress North America · 2026
Christin Pohl · Microsoft
World Congress Europe · 2026
Ekaterina Sirazitdinova
World Congress · 2023
Lerna Ekmekcioglu · Clockwork.io
Europe Virtual · 2026
Jobs that call for the skills explored in this talk.