





How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
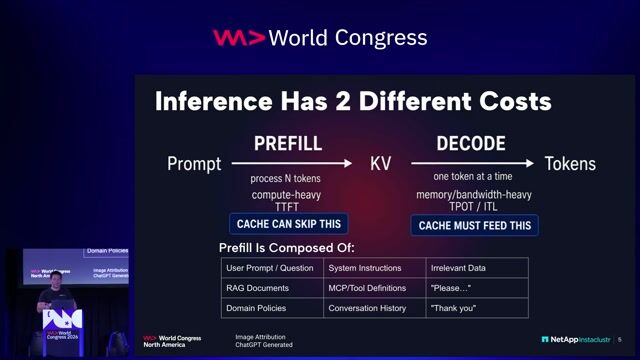
Running pre-fill and decode on the same GPU severely bottlenecks your AI throughput. Discover how cache-aware disaggregation and speculative decoding can drastically reduce latency and infrastructure costs.
Starting at 12:14 · Watch from the beginning
Checking access…
Playback and chapters load privately for Free videos.
5:58 min
 Hari Lingamagunta +3 · World Congress 2026 North America
1:47 min
 Deivids Vilkinsons +3 · World Congress 2026 Europe
3:20 min
 Erran Berger +1 · World Congress 2026 North America
1:52 min
 Neel Sundaresan +1 · World Congress 2026 Europe
2:37 min
 Julián Duque · World Congress 2025
1:47 min
 Yuval Dvir · World Congress 2026 North America
Fatih Kadir Akın · WordPress/Automattic
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Sagar Utekar
CrowdStrike
SRE

Omkar Srivastava
ADSK
Engineering Leader

Aakriti Aggarwal
IBM Research
Research Engineer

Bhavishya Pandit
66degrees
Leading AI Innovation

Aditya Joshi
Walmart
Senior Software Engineer

Bhavana Giri
Redis
Developer Advocate
Kushaagra Goyal · Rubrik
World Congress North America · 2026
Ankit Patel +1
World Congress North America · 2026
Christin Pohl · Microsoft
World Congress Europe · 2026
David vonThenen · NetApp
World Congress North America · 2026
Jobs that call for the skills explored in this talk.