
DC
Daniel Cranney
A Hands-On Developer Guide to Inference Engineering
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
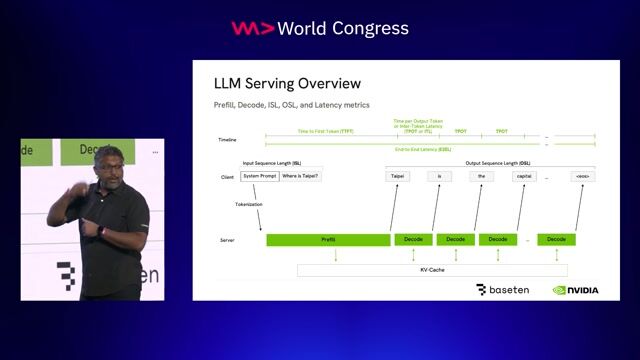
Scaling web apps once meant serving kilobytes of HTML. Today, inference engineers orchestrate terabytes of model weights and gigabytes of KV cache to deploy high-throughput generative AI.
Matching moments
5:58 min
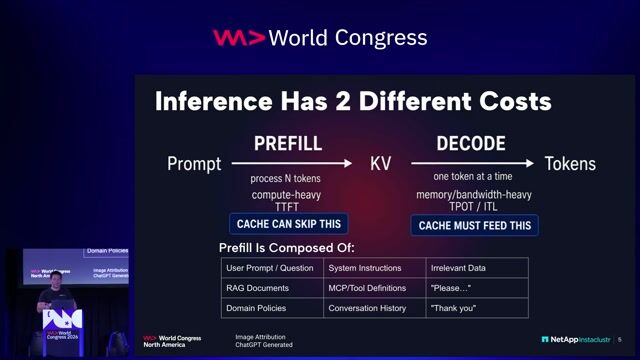
Architecting inference layers and meta harnesses to manage token costs
 Hari Lingamagunta +3 · World Congress 2026 North America
50 sec
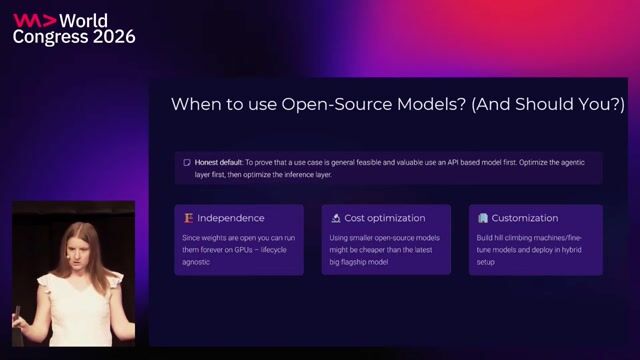
Key takeaways for optimizing open source inference engine deployments
 Legare Kerrison +1 · World Congress 2026 North America
1:52 min
Prioritizing developer user experience over raw model parameters
 Neel Sundaresan +1 · World Congress 2026 Europe
2:54 min
Optimizing infrastructure for agentic flows and inference
 Michael Kagan +1 · World Congress 2026 Europe
1:20 min
Engineering lessons for scaling high-performance AI infrastructure
 Wayne Liu · World Congress 2026 North America
1:24 min
Exploring open source inference tools for language model serving
Legare Kerrison +1 · World Congress 2026 North America
More from World Congress 2026 North America
Related videos
Related articles
BB
Benedikt Bischof

MH
Michael Hunger
N
Neo4j
BB
Benedikt Bischof

From learning to earning
Jobs that call for the skills explored in this talk.
26 days ago
Principal Software Engineer, AI Inference Cloud

ARM
Seattle, WA, United States
Expert
$262k
Pytorch
TensorRT
Kubernetes
26 days ago
Staff Software Engineer, AI Inference Cloud
ARM
Seattle, WA, United States
Expert
$209k–282k
Pytorch
TensorRT
Kubernetes
26 days ago
Principal Software Engineer, AI Inference Runtime
ARM
Seattle, WA, United States
Expert
$262k
Compilers
Low Latency
Concurrency
26 days ago
Staff Software Engineer, AI Inference Runtime
ARM
Seattle, WA, United States
Expert
$209k–282k
Compilers
Low Latency
Concurrency
about 2 months ago
•
Verified
LLM Training Engineer
Sciforium
San Francisco, United States
Expert
$155k–220k
Python
about 2 months ago
•
Verified
Distributed Training and Inference Engineer
Sciforium
San Francisco, United States
Expert
$190k–250k
Linux kernel