












DC
Daniel Cranney
KV Cache Is Not About Speed: It's About Surviving Inference Costs
- Discuss this with your agent
- Open in Claude
- Open in ChatGPT
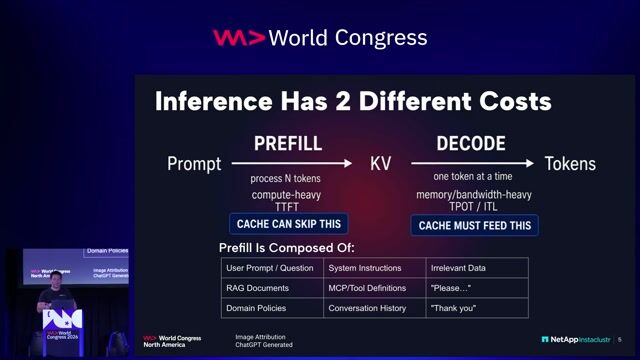
KV caching isn't about saving milliseconds on token generation. It's a survival strategy to prevent GPU memory exhaustion during the prefill phase and drastically slash LLM inference costs.
Checking access…
Playback and chapters load privately for Free videos.
Matching moments
3:31 min
Mitigating latency and memory walls with KV cache
 Kavya Sri Chennoju · World Congress 2026 North America
4:26 min
Optimizing AI infrastructure costs by maximizing token caching
 Liran Hason · World Congress 2026 Europe
2:34 min
Managing memory overhead by optimizing the KV cache
 Aditya Jayaprakash · World Congress 2026 North America
3:04 min
Addressing caching pitfalls with specialized tools and managed services
3:38 min
Optimizing unit economics through routing, caching, and compression
 Ed Huang +4 · World Congress 2026 North America
2:00 min
Navigating the layers of the language model inference stack
 Christin Pohl · World Congress 2026 Europe
More from World Congress 2026 North America
The Productivity Illusion: What AI Really Changed for Developers
Fatih Kadir Akın · WordPress/Automattic
Upcoming sessions on this topic
Starts in 5 days
Conference India 2026
November 25–26, 2026
Bengaluru, India
-
How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
 Purnima Kumari · DigitalOCean
Thu 26 Nov · Stage 2
-
Reuse knowledge for Agentic AI: Workshop on Agent Memory, lowering LLM costs, and reducing latency

 Bhavana Giri & Ashwin Hariharan
Thu 26 Nov · Room 9
-
Bypassing the GPU Tax: Smart Layer-7 Routing with Small Language Models (SLMs)
 Sagar Utekar · CrowdStrike
Thu 26 Nov · Stage 2
Related videos
Anatomy of an AI Request: Where Latency and Cost Are Really Born
Dan Fu · Together AI
World Congress North America · 2026
A Hands-On Developer Guide to Inference Engineering
Ankit Patel +1
World Congress North America · 2026
Tour de Force: Open-Source LLM Inference Optimization from Simple to Sophisticated
Christin Pohl · Microsoft
World Congress Europe · 2026
The New Bottleneck in Software Development
Aditya Jayaprakash · Blacksmith
World Congress North America · 2026
Fast, Cheap, and Accurate: Optimizing LLM Inference with vLLM and Quantization
World Congress North America · 2026
Compute for your AI model: GPUs, LPUs, TPUs and beyond..
Kushaagra Goyal · Rubrik
World Congress North America · 2026
Related articles
AB
Andrew Brookins
RD
Raphael De Lio
MH
Michael Hunger
N
Neo4j
YR
Yuri Romanenkov
DC
Daniel Cranney

From learning to earning
Jobs that call for the skills explored in this talk.
5 days ago
Lead Engineer, Google Cloud
PwC
Atlanta, GA, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
7 days ago
Lead Engineer, Google Cloud
PwC
Boca Raton, FL, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
5 days ago
Lead Engineer, Google Cloud
PwC
Toledo, OH, United States
Expert
$99k–232k
LangChain
Google Cloud
Generative AI
17 days ago
Senior Engineer, Google Cloud
PwC
Las Vegas, NV, United States
Expert
$77k–202k
LangChain
Google Cloud
Spring Cloud
17 days ago
Senior Engineer, Google Cloud
PwC
Kansas City, MO, United States
Expert
$77k–202k
LangChain
Google Cloud
Spring Cloud
17 days ago
Senior Engineer, Google Cloud
PwC
Phoenix, AZ, United States
Expert
$77k–202k
LangChain
Google Cloud
Spring Cloud