How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
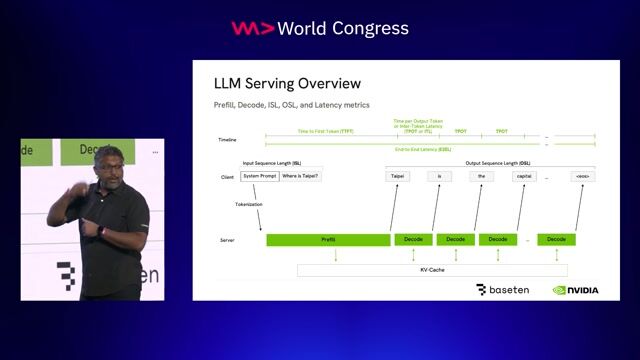
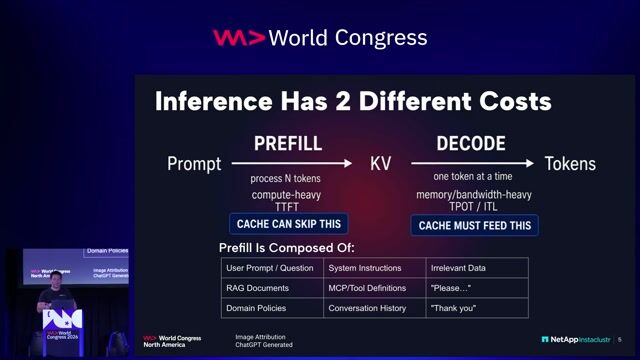
KV caching isn't about saving milliseconds on token generation. It's a survival strategy to prevent GPU memory exhaustion during the prefill phase and drastically slash LLM inference costs.
Checking access…
Playback and chapters load privately for Free videos.
3:31 min
 Kavya Sri Chennoju · World Congress 2026 North America
4:26 min
 Liran Hason · World Congress 2026 Europe
2:34 min
 Aditya Jayaprakash · World Congress 2026 North America
3:04 min
3:38 min
 Ed Huang +4 · World Congress 2026 North America
2:00 min
 Christin Pohl · World Congress 2026 Europe
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Suriya Prakash B
Red Hat
Principal Software Engineer

Aishwarya Mathuria
Adobe
Computer Scientist

Nishant Thakur
Adobe
Senior Computer Scientist

Vasundhara Shukla
Neo4j
Developer Advocate

Zaid Zaim
Neo4j
Developer Advocate | Microsoft AI MVP

Sajeetharan Sinnathurai
Microsoft
Principal Product Manager

Deepak Agrawal
Atlassian
Principal Software Engineer
Jobs that call for the skills explored in this talk.