





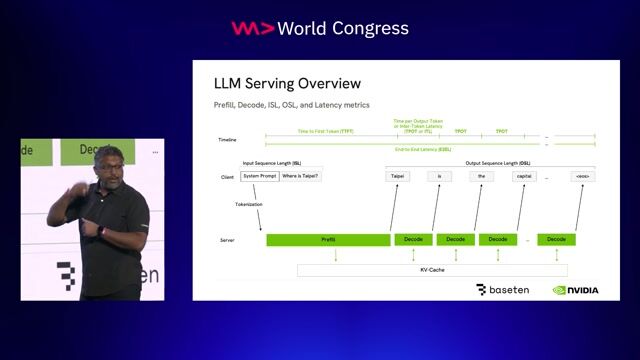
How 8 GPUs Became 16: Rethinking LLM Inference Through Parallelism, Memory, and Runtime Design
-

Purnima Kumari
DigitalOCean
Sr. Solutions Architect II
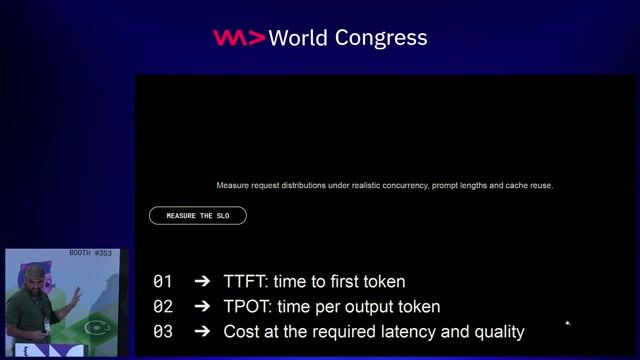
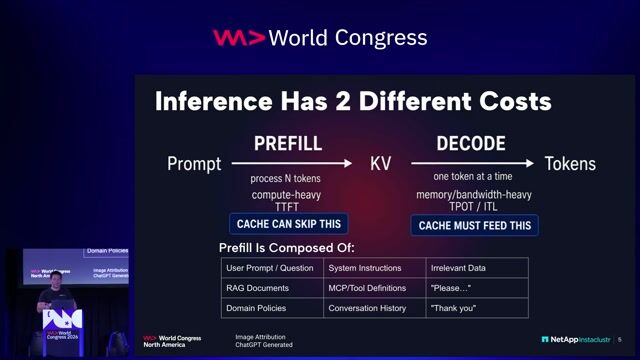
Scaling web apps once meant serving kilobytes of HTML. Today, inference engineers orchestrate terabytes of model weights and gigabytes of KV cache to deploy high-throughput generative AI.
Starting at 5:13 · Watch from the beginning
Checking access…
Playback and chapters load privately for Free videos.
5:58 min
 Hari Lingamagunta +3 · World Congress 2026 North America
50 sec
 Legare Kerrison +1 · World Congress 2026 North America
1:52 min
 Neel Sundaresan +1 · World Congress 2026 Europe
2:54 min
 Michael Kagan +1 · World Congress 2026 Europe
1:20 min
 Wayne Liu · World Congress 2026 North America
1:24 min
Legare Kerrison +1 · World Congress 2026 North America
Fatih Kadir Akın · WordPress/Automattic
Purnima Kumari
DigitalOCean
Sr. Solutions Architect II

Omkar Srivastava
ADSK
Engineering Leader

Sagar Utekar
CrowdStrike
SRE

Bhavana Giri
Redis
Developer Advocate

Aakriti Aggarwal
IBM Research
Research Engineer

Bhavishya Pandit
66degrees
Leading AI Innovation

Aditya Dua
GitHub
Senior Manager, Field Services, SAARC
Dan Fu · Together AI
World Congress North America · 2026
Christin Pohl · Microsoft
World Congress Europe · 2026
Kushaagra Goyal · Rubrik
World Congress North America · 2026
David vonThenen · NetApp
World Congress North America · 2026
Jobs that call for the skills explored in this talk.